Chapter 17Second-order optimization
We review in this chapter methods whose iterations take the form where is a stepsize and is a pre-conditioning matrix involving second-order derivatives.
17.1 Newton’s method
17.1.1 Variational perspective
We saw in Eq. (16.2) that gradient descent can be motivated from a variational perspective, in which we use a linear approximation of the objective around the current iterate, obtained from the current gradient. Similarly, if we have access not only to the gradient but also to the Hessian of the objective, we can use a quadratic approximation of the objective around the current iterate. More precisely, given a function , we may consider minimizing the second-order Taylor approximation of around the current iterate , Newton’s method simply iteratively minimizes this quadratic approximation around the current iteration , namely, If the Hessian is positive definite at , which we denote by , then the minimum is well-defined and unique (this is for example the case if is strictly convex). The iterates can then be written analytically as If the Hessian is not positive definite, the minimum may not be defined. Ignoring this issue and taking the analytical formulation could be dangerous, as it could amount to computing the maximum of the quadratic instead if, for example, the quadratic was strictly concave (i.e., ).
17.1.2 Regularized Newton method
A simple technique to circumvent this issue consists in adding a regularization term to the Hessian. Namely, from a variational viewpoint, we can add a proximity term , encouraging it to stay close to the current . The iterates of this regularized Newton method then take the form where controls the regularization strength. Assuming is strong enough to make positive-definite, we have where we defined the direction Other techniques to circumvent this issue include using cubic regularization and modifying the spectral decomposition of the Hessian, by thresholding the eigenvalues or taking their absolute values. We refer the interested reader to, e.g., (Nesterov, 2018; Wright and Nocedal, 1999) for more details.
17.1.3 Approximate direction
We observe a main impediment for implementing such a second-order optimization algorithm: even if we had access to the Hessian of the objective for free and this Hessian was positive definite, computing the exact direction in Eq. (17.2) requires computing an inverse-Hessian vector product (IHVP) with the gradient . Doing so exactly requires solving a linear system which a priori takes time. In practice, however, we can compute IHVPs approximately, as explained in Section 9.4.
17.1.4 Convergence guarantees
While implementing Newton’s method comes at a higher computational cost, it can also benefit from faster convergence rates. Briefly, if Newton’s method is initialized at a point close enough to the minimizer of a -strongly convex function with -Lipschitz continuous Hessian (namely ), then Newton’s method converges at a quadratic rate (Nesterov, 2018), that is, (see Section 15.5 for a brief introduction to performance guarantees). This is far superior to gradient descent. Such an efficiency motivated the development of interior point methods, that have been a breakthrough in constrained optimization, thanks to the use of log-barrier penalties (Nesterov, 2018).
17.1.5 Linesearch
In practice, we may not have access to an initial point close enough to the minimizer. In that case, even for strictly convex functions for which Newton’s steps are well-defined, taking may not ensure a decrease of the objective values. Nevertheless, the direction may define a descent direction as defined below.
Definition 17.1 (Descent direction)
A point defines a descent direction for an objective at , if there exists a positive stepsize such that If is differentiable, is a descent direction if .
For Newton’s method without regularization, is then a descent direction at , as long as and . If , choosing such that , also ensures that is a descent direction (as long as ). Newton’s method is then generally equipped with a linesearch method that attempts to take steps of the form with chosen as the largest stepsize among for until a sufficient decrease of the objective is satisfied such as, for , For strongly convex functions, such an implementation exhibits two phases: a first phase during which Newton’s steps are “damped” by using a stepsize and a second phase of super-fast convergence during which stepsizes are taken, and the objective decreases very fast. Even far from the optimum, Newton directions can advantageously adapt to the local geometry of the objective to speed up convergence compared to a regular gradient descent as explained below.
17.1.6 Geometric interpretation
To understand the efficiency of Newton’s method compared to gradient descent, consider the minimization of a simple quadratic for , as illustrated in Fig. 17.1. A gradient descent moves along the directions and its stepsize is limited by the variations in the first coordinate leading to some oscillations. If we were simply rescaling the gradient by , i.e., taking steps of the form the variations in both coordinates would be normalized to one and the stepsize could simply be chosen to to directly get . In other words, by adapting the geometry of the directions with the geometry induced by the objective, we can circumvent the oscillations.
That’s exactly what Newton’s method does by modifying the gradient direction using the inverse of the Hessian. Formally, at iteration , consider the modified objective with strictly convex and the inverse matrix square root of the Hessian. One easily verifies that a Newton step is equivalent to a gradient step on , that is, where In the geometry induced by , the objective is generally better conditioned as illustrated in Fig. 17.1. This explains the efficiency of Newton’s method. In particular for any strongly convex quadratic, a Newton step reaches the optimum in one iteration, while a gradient step can take many more iterations.
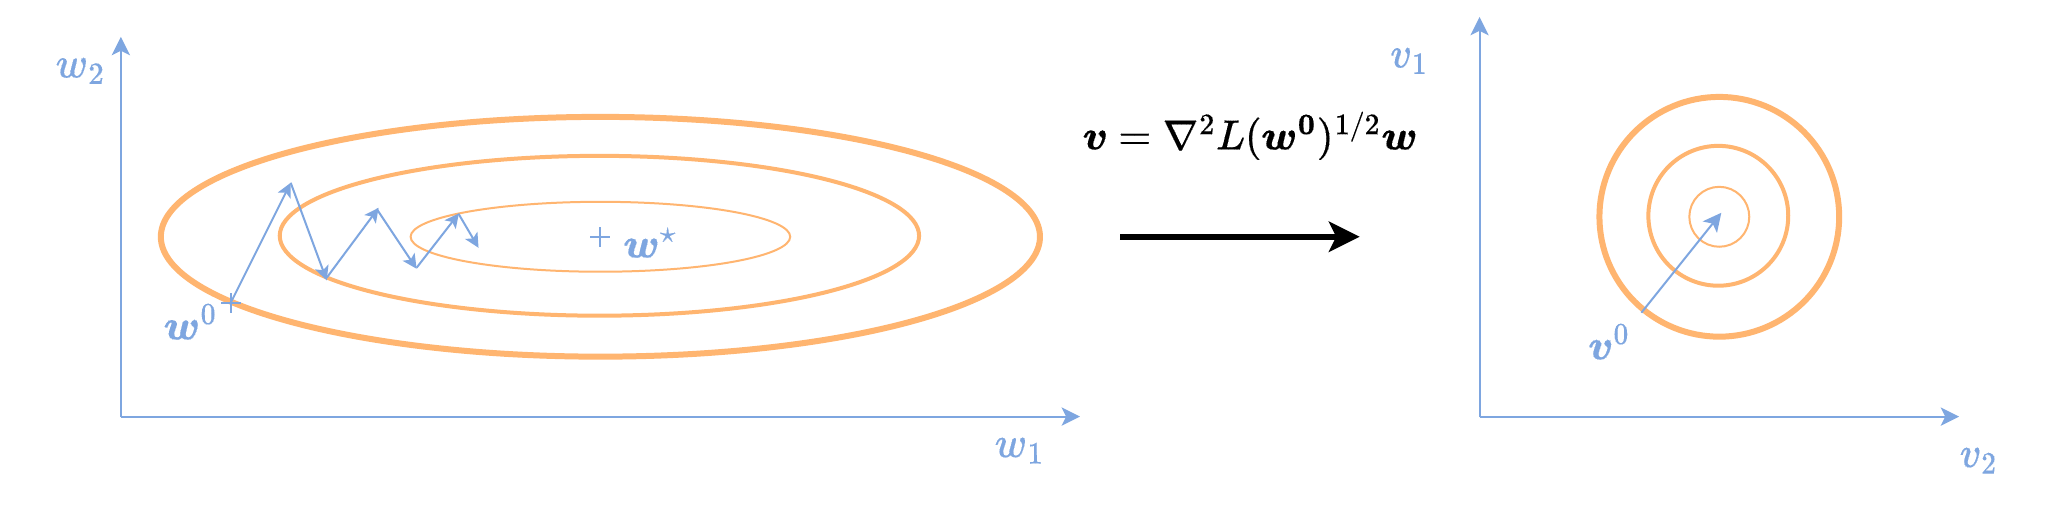
Figure 17.1: Left: Minimization of a quadratic by gradient descent. For , gradient descent typically oscillates. Right: minimization by Newton’s method amounts to changing the geometry of the problem to avoid oscillations.
17.1.7 Stochastic Newton’s method
Consider now an expected loss In that case, an estimate of the Hessian can be constructed just like for the gradient using that Les us then denote some stochastic estimates of the gradient and the Hessian, respectively, with independently drawn from or from mini-batch approximations with varying mini-batch sizes. One implementation of a stochastic Newton method can then be for such that and fixed or chosen to satisfy some sufficient decrease condition. We refer the interested reader to, e.g., (Xu et al., 2020), for more details and variants.
17.2 Gauss-Newton method
Newton’s method (17.1) is usually not properly defined for non-convex objective functions, since the Hessian may not be positive definite at the current iterate. We saw in Section 9.2 that the Gauss-Newton matrix can be used to define a positive-semidefinite approximation of the Hessian. Here, we revisit the Gauss-Newton method from a variational and partial linearization perspective. While the original Gauss-Newton method originates from nonlinear least-squares, we will first describe an extension to arbitrary convex loss functions, since it is both more general and easier to explain.
17.2.1 With exact outer function
Consider a composite objective of the form where is a convex function, such as a convex loss function applied on a given sample, and is a nonlinear function, such as a neural network with parameters , evaluated on the same sample. We saw that gradient descent and Newton’s method amount to using linear and quadratic approximations of around the current iterate , respectively. As a middle ground between the two, the Gauss-Newton method uses the linearization of around but keeps as is to obtain the objective where we defined the shorthands and . We call the partial linearization of at , as opposed to the full linearization of used in gradient descent.
Since the composition of a convex function and of linear function is convex, this objective is convex even if is nonconvex. In practice, we often add a proximity term as regularization to define We can see this update as an approximation of the proximal point update where has been replaced by its partial linearization. Solving Eq. (17.3) using gradient-based solvers requires computing the gradient of , which is . Computing this gradient by autodiff therefore requires performing a forward pass to compute the JVP and a backward pass to compute the VJP . See Section 2.3 for an introduction to these operators and Chapter 8 for an introduction to autodiff.
The Gauss-Newton method with arbitrary convex outer loss is often called modified Gauss-Newton (Nesterov, 2007) or prox-linear (Drusvyatskiy and Paquette, 2019). The classical Gauss-Newton and Levenberg-Marquardt (Levenberg, 1944; Marquardt, 1963) methods originate from nonlinear least-squares and are recovered when is quadratic (Kelley, 1995), such as , for some reference target. The Gauss-Newton method corresponds classically to not using regularization (i.e., ) and the Levenberg-Marquardt method uses regularization (usually called damping, potentially changing across iterations). See e.g., (Messerer et al., 2021), for a survey of different variants.
17.2.2 With approximate outer function
Another variant of the Gauss-Newton method consists in replacing the convex loss with its quadratic approximation around , to define the update Notice that has been replaced by its quadratic approximation . This objective is always a convex quadratic, unlike the objective of the Newton method in Eq. (17.1), which is a priori a nonconvex quadratic, if is nonlinear. Simple calculations show that where The closed form solution is where we used the (generalized) Gauss-Newton matrix of , defined in Section 9.2.
17.2.3 Linesearch
Similarly to Newton’s method, the iterates of a Gauss-Newton method may diverge when used alone. However, the direction defines a descent direction for any and can be combined with a stepsize (typically chosen using a linesearch) to obtain iterates of the form
17.2.4 Stochastic Gauss-Newton
In deep learning, the objective generally consists in an expectation over samples of the composition between a loss function and a network function: where denotes a sample pair of input with associated label . In that case, as already studied in Section 9.2, the Gauss-Newton matrix is the expectation of the individual Gauss-Newton matrices We can estimate the gradient and the Gauss-Newton matrix by, respectively, , and for or using mini-batch approximations. A stochastic Gauss-Newton method therefore performs iterates for and fixed or selected to satisfy some criterion.
17.3 Natural gradient descent
Natural gradient descent (Amari, 1998) follows a similar principle as gradient descent: linearize the objective around the current iterate and minimize this approximation together with a proximity term. It differs from gradient descent in the choice of the proximity term: rather than using a squared Euclidean distance between the parameters, it uses a Kullback-Leibler divergence between the probability distributions these parameters define.
Negative log-likelihood
We consider objectives of the form where is an unknown data distribution (but from which we can sample) and where is a probability distribution parameterized by . As reviewed in Chapter 3, the negative log-likelihood can be used as a loss function (many loss functions can be seen from this perspective, including the squared and logistic loss functions). In the unsupervised setting, where , we simply use as is. In the supervised setting, where , we use the product rule to parameterize as where is the marginal distribution for , is the PMF/PDF of a probability distribution and is for instance a neural network with parameters and input .
17.3.1 Variational perspective
Natural gradient descent is motivated by updates of the form where is the Kullback-Leibler (KL) divergence. Unlike gradient descent, the proximity term is therefore between the current distribution and a candidate probability distribution . The above problem is intractable in general, as the KL may not have a closed form. Nevertheless, its quadratic approximation can be shown (Amari, 1998) to admit a simple form, where we used the Fisher information matrix , studied in Section 9.3. Equipped with this quadratic approximation of the KL divergence, natural gradient descent amounts to computing iterates as where a quadratic proximity term was added to ensure a unique solution. This is a strictly convex problem as is positive semi-definite. The closed-form solution is Because the Gauss-Newton and Fisher information matrices are equivalent when is an exponential family distribution (Proposition 9.6), the Gauss-Newton and natural gradient methods coincide in this case.
17.3.2 Stochastic natural gradient descent
In practice, we may not have access to in closed form as it is an expectation over . Moreover, may not be computable in closed form either. To estimate the Fisher information matrix, we can use that (see Section 9.3) using the shorthand , We can then build estimates and for sampled from and sampled from . A stochastic natural gradient descent can then be implemented as where is a stepsize, possibly chosen by linesearch.
In deep learning, the product with the inverse Fisher or Gauss-Newton matrices can remain costly to compute. Several approximations have been proposed, such as KFAC (Botev et al., 2017; Martens and Grosse, 2015), which uses a computationally efficient structural approximation to these matrices.
17.4 Quasi-Newton methods
17.4.1 BFGS
A celebrated example of quasi-Newton method is the BFGS method (Broyden, 1970; Fletcher, 1970; Goldfarb, 1970; Shanno, 1970), whose acronym follows from its authors’ names. The rationale of the BFGS update stems once again from a variational viewpoint. We wish to build a simple quadratic model of the objective for some built along the iterations rather than taken as . One desirable property of such a quadratic model would be that its gradients at consecutive iterates match the gradients of the original function, i.e., and . A simpler condition, called the secant condition consists in considering the differences of these vectors, that is, ensuring that for . Building , a surrogate of the inverse of the Hessian satisfying the secant equation, can then be done as where A typical implementation of BFGS stores in memory, which is prohibitive when is large.
17.4.2 Limited-memory BFGS
In practice, the limited-memory counterpart of BFGS, called LBFGS (Liu and Nocedal, 1989), is often preferred. The key observation of LBFGS is that we do not need to materialize in memory: we only need to multiply it with the gradient . That is, we can see as a linear map. Fortunately, the product between and any vector can be computed efficiently if we store in memory. In practice, a small history of past values is used to reduce memory and computational cost. Because LBFGS has the benefits of second-order-like methods with much reduced cost, it has become a de-facto algorithm, outperforming most other algorithms for medium-scale problems without particular structure (Liu and Nocedal, 1989).
17.5 Approximate Hessian diagonal inverse preconditioners
One application of the approximations of the Hessian diagonal developed in Section 9.7 is to obtain cheap approximations of the Hessian diagonal inverse, Such a scaling would for instance be sufficient to make the quadratic example presented in Fig. 17.1 work. Many optimization algorithms, including the popular ADAM, can be viewed as using a preconditioner that approximates the inverse of the Hessian’s diagonal.
17.6 Summary
We reviewed Newton’s method, the Gauss-Newton method, natural gradient descent, quasi-Newton methods and preconditioning methods.
We adopted a variational viewpoint, where the method’s next iterate is computed as the solution of a trade-off between minimizing an approximation of the function (linear, partially linear, quadratic) and a proximity term (squared Euclidean, KL).
All methods were shown to use iterates of the form but have different trade-offs between the cost it takes to evaluate and the richness of the information used about .