Chapter 11Differentiating through optimization
In this chapter, we study how to differentiate through optimization problems, and more generally through nonlinear systems of equations.
11.1 Implicit functions
Implicit functions are functions that do not enjoy an explicit decomposition into elementary functions, for which automatic differentiation, as studied in Chapter 8, can therefore not be directly applied. We describe in this chapter techniques to differentiate through such functions and how to integrate them into an autodiff framework.
Formally, we will denote an implicit function by , where . One question is then how to compute the Jacobian . As a first application one can consider sensitivity analysis of a system. For example, could correspond to the equilibrium state of a physical system and in this case, would tell us about the sensitivity of the system to some parameters .
11.1.1 Optimization problems
Another example is a function implicitly defined as the solution (assumed unique) of an optimization problem where and denotes a constraint set. Note that we use an for convenience, but the same applies when using an .
11.1.2 Nonlinear equations
More generally, can be defined as the root of some function , i.e., is implicitly defined as the value satisfying the (potentially nonlinear) system of equations for all .
11.1.3 Application to bilevel optimization
Besides sensitivity analysis, another example of application is bilevel optimization. Many times, we want to minimize a function defined as the composition of a fixed function and the solution of an optimization problem. Formally, let . We consider the composition defined as This includes for instance hyperparameter optimization, where is an inner log-likelihood objective, is an outer validation loss, are model parameters and are model hyperparameters, such as regularization strength, as illustrated in Fig. 11.1. To minimize , one generally resorts to a gradient descent scheme w.r.t. , which requires computing . Assuming that is differentiable at , by the chain rule, we obtain the Jacobian Using (see Remark 2.4), we obtain the gradient The only problematic term is , as it requires argmax differentiation. Indeed, most of the time, there is no explicit formula for and it does not decompose into elementary functions.
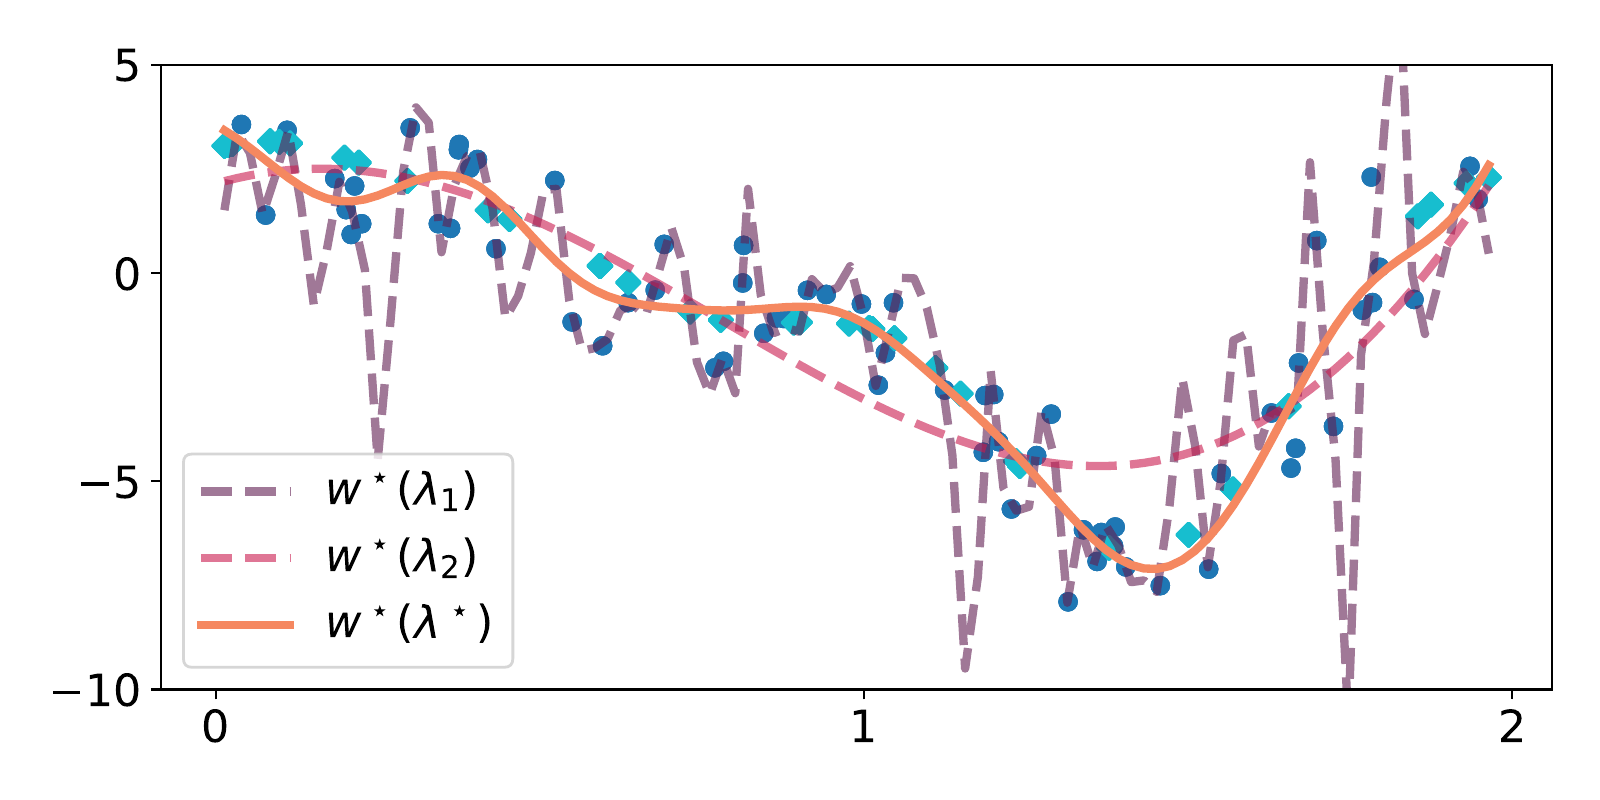
Figure 11.1: Hyperparameter optimization in nonlinear regression can be cast as a bi-level optimization problem. Each line corresponds to the estimator obtained by fitting some training data (in blue circles) using a different hyperparameter . Formally, denoting the training objective, the estimators are . The goal is to find the best hyperparameter that fits some validation data (here in cyan diamonds), that is, minimizing , where is the validation objective. A too small leads to overfitting the training objective and performs badly on validation objective. Conversely, a larger underfits both training and validation objectives. The optimal parameter minimizes the validation objective and may be obtained by iterating gradient descent w.r.t. . This requires gradients of w.r.t. .
11.2 Envelope theorems
In the special case , the composition defined in Eq. (11.1) is simply given by That is, we no longer need argmax differentiation, but only max differentiation, which, as we shall now see is much easier. The function is often called a value function (Fleming and Rishel, 2012). The reason for the name “envelope” is illustrated in Fig. 11.2. We emphasize that there is not one, but several envelope theorems, depending on the assumptions on .
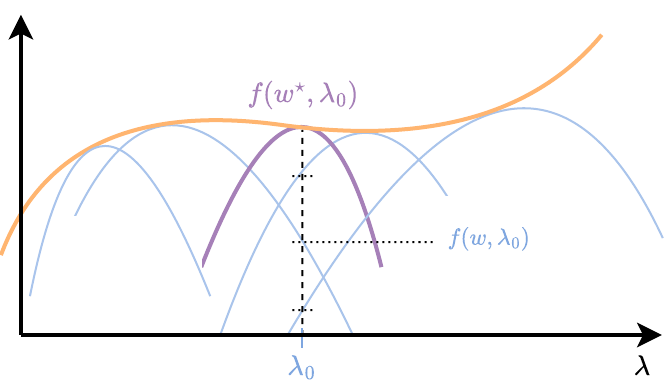
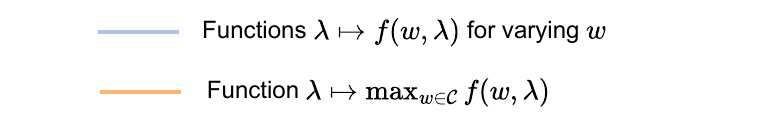
Figure 11.2: The graph of is the upper-envelope of the graphs of the functions for all .
11.2.1 Bertsekas’ theorem
The following theorem is due to Bertsekas (1997, Proposition B.25).
Theorem 11.1 (Bertsekas’ theorem)
Let and where is concave in and is a compact convex set. If the maximum is unique, then the function is differentiable with gradient If furthermore is convex in , then is convex.
A variant of the theorem can be stated when .
Theorem 11.2 (Unbounded case)
Suppose . If is strongly concave in , then the function is differentiable with gradient If furthermore is convex in , then is convex.
Informally, Theorem 11.1 and Theorem 11.2 mean that we can treat as if it were a constant of . In other words, we do not need to differentiate through , even though it depends on .
Remark 11.1 (Historical note)
Bertsekas’ theorem or its unbounded variant are often incorrectly cited as Danskin’s theorem in the machine learning literature, because Bertsekas himself called it that way (Bertsekas, 1997, Proposition B.25). However, because the assumptions differ, they should rather be thought as variants or corollaries of Danskin’s original theorem. See Section 11.2.3 for more details.
We now illustrate Theorem 11.2, to differentiate through a minimum, , assuming is strongly convex in .
Example 11.1 (Differentiating the minimum of a convex quadratic)
Let us define , where and . The derivative of w.r.t. is . The second derivative of w.r.t. is . Therefore is strongly convex in . Let be the minimum of in . Setting to zero, we get . The derivative of w.r.t. is . From Theorem 11.2, we have . Let us check that the derivative is indeed correct. Plugging back into , we get the analytical formula . Using , we indeed obtain the same expression for .
Theorem 11.1 has a simple interpretation for functions that are affine in as shown below.
Example 11.2 (Convex conjugate)
Let with convex. We then have , where denotes the convex conjugate of . Since is convex and assuming is convex compact, the conditions of Theorem 11.1 are met. Since , we obtain . In other words, in this special case, the gradient of the max is equal to the argmax. This is due to the fact that is affine in .
Another application is saddle point optimization.
Example 11.3 (Saddle point problem)
Consider the saddle point problem . If it is difficult to minimize w.r.t. but easy to maximize w.r.t. , we can rewrite the problem as , where , and use to perform (projected) gradient descent w.r.t. .
11.2.2 Rockafellar’s theorem
A related theorem (Rockafellar and Wets, 2009, Theorem 10.31) can be proved under different assumptions on .
Theorem 11.3 (Rockafellar’s envelope theorem)
Let and be a compact convex set. Let and If is continuously differentiable in for all , is continuous and the maximum is unique, then the function is differentiable with gradient
Compared to Bertsekas’ theorem, Rockafellar’s theorem does not require to be concave in , but it requires stronger assumptions on the differentiability of .
11.2.3 Danskin’s theorem
Finally, we state Danskin’s original theorem (Danskin, 1966).
Theorem 11.4 (Danskin’s theorem)
Let be a compact topological space. Let be continuous and continuously differentiable with respect to . Let the value function and the set of maximizers be defined as Then, the directional derivative of at in direction , denoted , exists and is given by
We sum up envelope theorems and their assumptions in Table 11.1.
Table 11.1: Comparison of different envelope theorems.
| Theorem | Unique ? | Concave in ? | Smooth in ? | Result |
|---|---|---|---|---|
| Danskin | No | No | No | Dir. Deriv. |
| Bertsekas | Yes | Yes | No | Gradient |
| Rockafellar | Yes | No | Yes | Gradient |
11.3 Implicit function theorem
11.3.1 Univariate functions
The implicit function theorem (IFT) provides conditions under which an implicit relationship of the form can be rewritten as a function locally, and provides a way to compute its derivative w.r.t. .
Theorem 11.5 (Implicit function theorem, univariate case)
Let
. Assume is a continuously differentiable function in a neighborhood of such that and . Then there exists a neighborhood of in which there is a function such that
,
for all in the neighborhood ,
.
We postpone the proof to the multivariate case and begin with a classical example of application of the theorem.
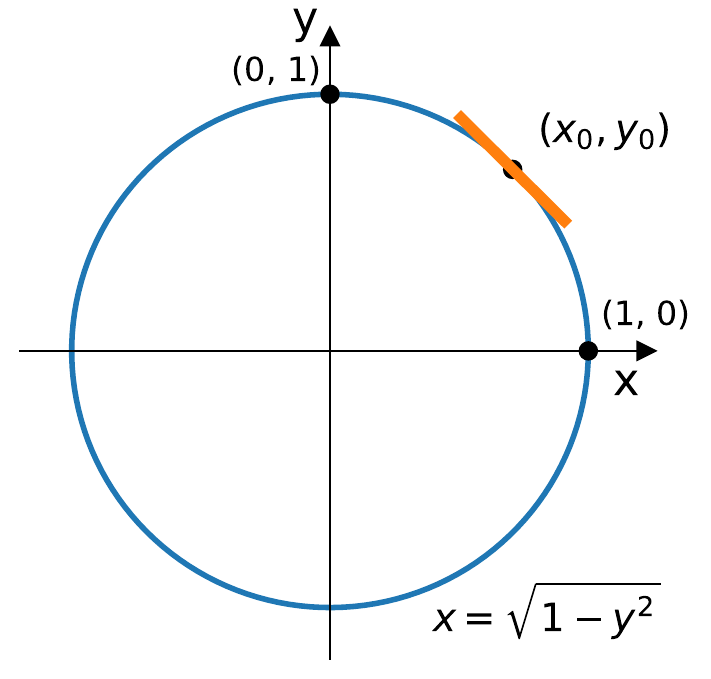
Figure 11.3: The circle equation is not a function from to , as there are always two possible values, or . However, locally around some point , e.g., such that and (upper-right quadrant), the function is well-defined. The implicit function theorem gives conditions for such a function to exist locally and provides a way to compute its derivative.
Example 11.4 (Equation of the unit circle)
We use and for clarity. Let . In general, we cannot rewrite the unit circle equation as a function from to , because for every , there are always two possible values, namely, or . However, locally around some point , e.g., such that and (upper-right quadrant), the function is well-defined. Using and , we get in that neighborhood (the upper right quadrant in this case). This is indeed the same derivative expression as if we used the chain rule on and is well-defined on .
In the above simple example, we can easily derive an explicit function relating to in a given neighborhood, but this is not always the case. The IFT gives us conditions guaranteeing that such function exists and a way to differentiate it, but not a way to construct such a function. In fact, finding such that typically involves a root finding algorithm, an optimization algorithm, a nonlinear system solver, etc.
Example 11.5 (Polynomial)
Let . According to the Abel-Ruffini theorem (Tignol, 2015), quintics (polynomials of degree ) do not enjoy roots in terms of radicals and one must resort to numerical root finding. In addition, odd-degree polynomials have real roots. Moreover, is strictly positive. Therefore, by the intermediate value theorem, there must be only one root such that . This unique root can for example be found by bisection. Using the IFT, its derivative is found to be .
While an implicit function is differentiable at a point if the assumptions of the IFT hold in a neighborhood of that point, the reciprocal is not true: failure of the IFT assumptions does not necessarily mean that the implicit function is not differentiable, as we now illustrate.
Example 11.6 (IFT conditions are not necessary for differentiability)
Consider . We clearly have that if we define , the identity function. It is clearly differentiable for all , yet the assumptions of the IFT fail, since we have and therefore .
11.3.2 Multivariate functions
We now present the IFT in the general multivariate setting. Informally, if , then by the chain rule, we have meaning that the Jacobian , assuming that it exists, satisfies The IFT gives us conditions for the existence of .
Theorem 11.6 (Implicit function theorem, multivariate case)
Let us define . Assume is a continuously differentiable function in a neighborhood of such that and is invertible, i.e., its determinant is nonzero. Then there exists a neighborhood of in which there is a function such that
,
for all in the neighborhood,
We begin with a simple unconstrained optimization algorithm.
Example 11.7 (Unconstrained optimization)
Assume we want to differentiate through , where is strictly convex in , which ensures that the solution is unique. From the stationary conditions, if we define , then is uniquely characterized as the root of in the first argument, i.e., . We have , the Hessian of in , and , the cross derivatives of in and . Therefore, assuming that the Hessian is well-defined and invertible at , we can use the IFT to differentiate through and obtain .
Next, we generalize the previous example, by allowing constraints in the optimization problem.
Example 11.8 (Constrained optimization)
Now, assume we want to differentiate through , where is strictly convex in and is a convex set. A solution is characterized by the fixed point equation , for any , where is the Euclidean projection of onto . Therefore, is the root of (see Chapter 16). We can differentiate through using the IFT, assuming that the conditions of the theorem apply. Note that requires the expression of the Jacobian . Fortunately, and its Jacobian are easy to compute for many sets (Blondel et al., 2021).
11.3.3 JVP and VJP of implicit functions
To integrate an implicit function in an autodiff framework, we need to be able to compute its JVP or VJP. This is the purpose of the next proposition.
Proposition 11.1 (JVP and VJP of implicit functions)
Let be a function implicitly defined as the solution of , for some function . Define Assume the assumptions of the IFT hold. The JVP in the input direction is obtained by solving the linear system The VJP in the output direction is obtained by solving the linear system Using the solution , we get
Note that in the above linear systems, we can access and as linear maps, the JVPs of . Their adjoints, and , correspond to the VJPs of . To solve these systems, we can therefore use matrix-free solvers as detailed in Section 9.4. For example, when is symmetric positive semi-definite, we can use the conjugate gradient method (Hestenes et al., 1952). When is not symmetric positive definite, we can use GMRES (Saad and Schultz, 1986) or BiCGSTAB (Vorst and Vorst, 1992).
11.3.4 Proof of the implicit function theorem
We prove the theorem using the inverse function theorem presented in Theorem 11.7. Define which goes from onto . The Jacobian of is So at , we have since we assumed invertible. By the inverse function theorem, the function is then invertible in a neighborhood of . In particular, it is invertible in . The solution of the implicit equation in a neighborhood of is then . By the inverse function theorem, is continuously differentiable inverse and so is . The derivative is obtained from the differential of the inverse as and by the inverse function theorem, we have Using the block matrix inversion formula, we therefore obtain we get the claimed expression. Though we expressed the proof in terms of Jacobians and matrices, the result naturally holds for the corresponding linear operators, JVPs, VJPs, and their inverses.
11.4 Adjoint state method
11.4.1 Differentiating nonlinear equations
We describe in this section the adjoint state method (a.k.a. adjoint method, method of adjoints, adjoint sensitivity method). The method can be used to compute the gradient of the composition of an explicit function and an implicit function, defined through an equality constraint (e.g., a nonlinear equation). The method dates back to Céa (1986).
Suppose a variable (which corresponds to a state in optimal control) is implicitly defined given some parameters through the (potentially nonlinear) equation , where . Assuming is uniquely determined for all , this defines an implicit function from to such that . Given an objective function , the goal of the adjoint state method is then to compute the gradient of However, this is not trivial as is an implicit function. For instance, this can be used to convert the equality-constrained problem into the unconstrained problem Access to allows us to solve this problem by gradient descent.
Proposition 11.2 (Adjoint state method)
Let be a mapping defining constraints of the form . Assume that for each , there exists a unique satisfying and that is differentiable. The gradient of for some differentiable function , is given by where is the solution of the linear system
As shown in the proof below, corresponds to a Lagrange multiplier. The linear system can be solved using matrix-free solvers.
11.4.2 Relation with envelope theorems
Because is uniquely determined for any by , we can alternatively rewrite as the trivial minimization or maximization, Therefore, the adjoint state method can be seen as an envelope theorem for computing , for the case when is involved in both the objective function and in the equality constraint.
11.4.3 Proof using the method of Lagrange multipliers
Classically, the adjoint state method is derived using the method of Lagrange multipliers. Let us introduce the Lagrangian associated with and , where is the Lagrange multiplier associated with the equality constraint . In the optimal control literature, is often called the adjoint variable or adjoint state. The gradients of the Lagrangian are where are the adjoint operators. Setting to zero gives the constraint . Setting to zero gives the so-called adjoint state equation Solving this linear system w.r.t. at gives the adjoint variable . We then get which concludes the proof.
11.4.4 Proof using the implicit function theorem
A more direct proof is possible thanks to the implicit function theorem (Section 11.3). Using the chain rule, we get where is the VJP of , a linear map from to .
Computationally, the main difficulty is to apply to the vector . Using the implicit function theorem (Section 11.3) on the implicit function , and Proposition 11.1, we get the linear system , where is a linear map from to . After solving for , we get , where is a linear map from to . Putting everything together, we get
11.4.5 Reverse mode as adjoint method with backsubstitution
In this section, we revisit reverse-mode autodiff from the perspective of the adjoint state method. For clarity, we focus our exposition on feedforward networks with input and network weights , defined by Here we focus on gradients with respect to the parameters , hence the notation . We can use the adjoint state method to recover reverse-mode autodiff, and prove its correctness in the process. While we focus for simplicity on feedforward networks, our exposition can be generalized to computation graphs.
Feedforward networks as the solution of a nonlinear equation
While we defined the set of intermediate computations as a sequence of operations, they can also be defined as the unique solution of the nonlinear equation , where This defines an implicit function , the solution of this nonlinear system, which is given by the variables defined in Eq. (11.2). The output of the feedforward network is then .
In machine learning, the final layer is typically fed into a loss , to define Note that an alternative is to write as
More generally, if we just want to compute the VJP of in some direction , we can define the scalar-valued function so that Let us define as (gradient of the loss case) or (VJP of in the direction case). Using the adjoint state method, we know that the gradient of this objective is obtained as for the solution of the linear system
Solving the linear system using backsubtitution
The JVP of the constraint function at , materialized as a matrix, takes the form of a block lower-triangular matrix where . Crucially the triangular structure of the JVP stems from the fact that each intermediate activation only depends on the past intermediate activations. Therefore, the constraints, corresponding to the lines of the Jacobian, cannot introduce non-zero values beyond its diagonal. The VJP takes the form of a block upper-triangular matrix Solving an upper triangular system like can then be done efficiently by backsubstitution. Starting from the last adjoint state , we can compute each adjoint state from that computed at . Namely, for , we have The VJPs with respect to the parameters are then obtained by recovering reverse-mode autodiff.
The Lagrangian perspective of backpropagation for networks with separate parameters is well-known; see for instance LeCun (1988) or Recht (2016). The Lagrangian perspective of backpropagation through time (Werbos, 1990) for networks with shared parameter is discussed for instance by Franceschi et al. (2017). Our exposition uses the adjoint state method, which can itself be proved either using the method of Lagrange multipliers (Section 11.4.3) or by the implicit function theorem (Section 11.4.4), combined with backsubtitution for solving the upper-triangular linear system. Past works often minimize over but we do not require this, as gradients are not necessarily used for optimization. Our exposition also supports computing the VJP of any vector-valued function , while existing works derive the gradient of a scalar-valued loss function.
11.5 Inverse function theorem
11.5.1 Differentiating inverse functions
In some cases (see for instance Section 12.4.4), it is useful to compute the Jacobian of an inverse function . The inverse function theorem below allows us to relate the Jacobian of with the Jacobian of .
Theorem 11.7 (Inverse function theorem)
Assume is continuously differentiable with invertible Jacobian at . Then is bijective from a neighborhood of to a neighborhood of . Moreover, the inverse is continuously differentiable near and the Jacobian of the inverse is with .
11.5.2 Link with the implicit function theorem
The inverse function theorem can be used to prove the implicit function theorem; see proof of Theorem 11.6. Conversely, recall that, in order to use the implicit function theorem, we need to choose a root objective . If we set and , with , then we have that the root satisfying is exactly . Moreover, and . By applying the implicit function theorem with this , we indeed recover the inverse function theorem.
11.5.3 Proof of inverse function theorem
We first give a proof of the formula assuming that is well-defined and continuously differentiable in a neighborhood of . In that case, we have for any in a neighborhood of , Differentiating both sides w.r.t. , we get where is the identity function in . In particular, for we recover the formula presented in the statement.
Now, it remains to show that invertibility of the JVP ensures that the function is invertible in a neighborhood of and that the inverse is continuously differentiable. For that, denote such that is well-defined by definition. is invertible with continuously differentiable inverse, if and only if is invertible with continuously differentiable inverse. So without loss of generality, we consider , , .
As is continuously differentiable, there exists a neighborhood on which we have . In this neighborhood, the function is contractive by the mean value theorem with contraction factor . For any such that , the sequence remains in and converges (since it is a Cauchy sequence by the contraction of ) to a unique fixed point satisfying . This shows the existence of the inverse in the neighborhood of onto .
We tackle now the differentiability (hence the continuity) of . For any in the neighborhood of with inverse , the JVP of at satisfies by assumption . Hence, defines a convergent series and one verifies easily that , that is is invertible and . To compute the JVP of the inverse, we consider then as the candidate JVP and examine Denote then such that . As is -contractive in , we have . So . We then get As , we have and so . Hence, is differentiable with JVP . This shows that is continuous and so is continuous as a composition of continuous functions.
11.6 Summary
Implicit functions are functions that cannot be decomposed into elementary operations and for which autodiff can therefore not be directly applied. Examples are optimization problems and nonlinear equations.
Envelope theorems can be used for differentiating through the min or max value (not solution) of a function.
More generally, the implicit function theorem allows us to differentiate through implicit functions. It gives conditions for the existence of derivatives and how to obtain them.
The adjoint state method can be used to obtain the gradient of the composition of an explicit function and of an implicit function, specified by equality constraints. It can be used to prove the correctness of reverse-mode autodiff.
The inverse function theorem can be used to differentiate function inverses.
In a sense, the implicit function theorem can be thought of as the mother theorem, as it can be used to prove envelope theorems, the adjoint state method and the inverse function theorem.