Chapter 7Finite differences
One of the simplest ways to numerically compute derivatives is to use finite differences, which approximate the infinitesimal definition of derivatives. Finite differences only require function evaluations, and can therefore work with blackbox functions: they ignore the compositional structure of functions. Without loss of generality, our exposition focuses on computing directional derivatives , for a function , evaluated at , in the direction .
7.1 Forward differences
From Definition 2.4 and Definition 2.13, the directional derivative and more generally the JVP are defined as a limit, This suggests that we can approximate the directional derivative and the JVP using for some . This formula is called a forward difference.
To measure the error incurred by this approximation, we use Landau’s notation.
Remark 7.1 (Big notation)
For two functions and , we write if the ratio is bounded as . For example, we write as . In the following, unless otherwise specified, we compare limits as . We observe that implies . However, Landau’s notation provides finer practical interpretations than Landau’s notation. For example, if , then we know its upper bound scales quadratically, meaning that reducing by a factor of 2 reduces this bound by a factor of 4. Knowing only that does not allow us to make such a concrete statement, because it merely dictates that decays strictly faster than , without providing a specific bounding rate or scaling factor for that decay. For numerical analysis, Landau’s notation is therefore preferable.
From the Taylor expansion in Section 2.5.4, we indeed have so that The error incurred by choosing a finite rather than infinitesimal in the forward difference formula is called the truncation error. The Taylor approximation above shows that this error is of the order of .
However, we cannot choose a too small value of , because the evaluation of the function on a computer rounds the value of to machine precision. Mathematically, a scalar-valued function evaluated on a computer becomes a function such that , where denotes the closest integer of and is the machine precision, i.e., the smallest non-zero real number encoded by the machine. This means that the difference evaluated on a computer is prone to round-off error of the order of . We illustrate the trade-off between truncation and round-off errors in Fig. 7.1.
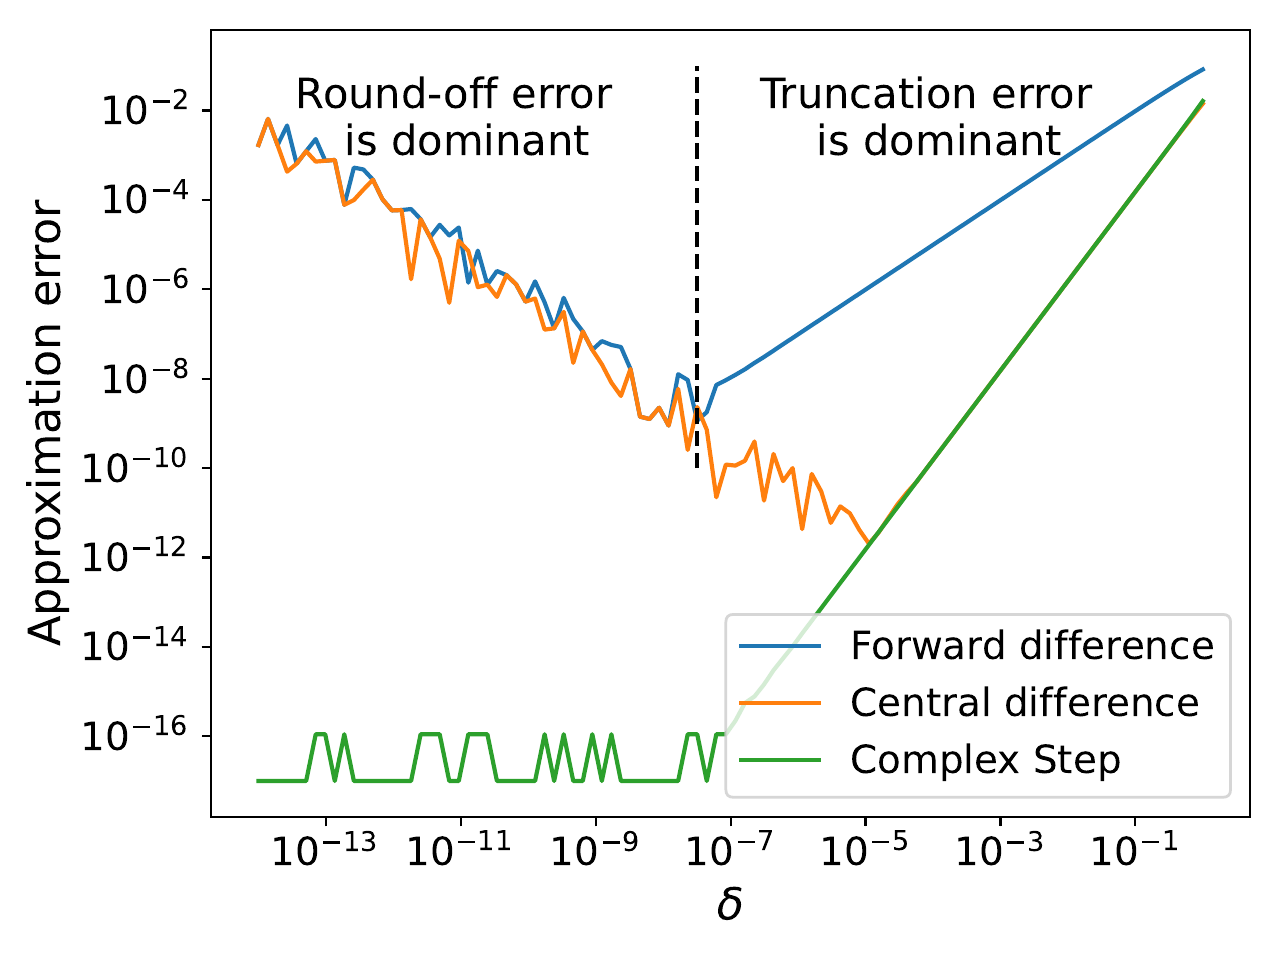
Figure 7.1: Numerical differentiation of , to approximate at . The forward and central difference methods induce both truncation error (for large ) and round-off error (for small ). The complex step method enjoys smaller round-off error.
7.2 Backward differences
As an alternative, we can approximate the directional derivative and the JVP by for some . This formula is called a backward difference. From the Taylor expansion in Section 2.5.4, we easily verify that , so that the truncation error is the same as for the forward difference.
7.3 Central differences
Rather than using an asymmetric formula to approximate the derivative, as in forward and backward differences, we can use a symmetric formula for some . This formula is called a central difference. From the Taylor expansion in Section 2.5.4, we have so that We see that the terms corresponding to derivatives of even order canceled out, allowing the formula to achieve truncation error. For any , the truncation error of the central difference is much smaller than the one of the forward or backward differences as confirmed empirically in Fig. 7.1.
7.4 Higher-accuracy finite differences
The truncation error can be further reduced by making use of additional function evaluations. One can generalize the forward difference scheme by a formula of the form requiring evaluations. To select the and reach a truncation error of order , we can use a Taylor expansion on each term of the sum to get By grouping the terms in the sum for each order of derivative, we obtain a set of equations to be satisfied by the coefficients , that is, This system of equations can be solved analytically to derive the coefficients. Backward differences can be generalized similarly by using . Similarly, the central difference scheme can be generalized by using to reach a truncation error of order . Solving for the coefficients as above reveals that . Therefore, only evaluations are necessary.
7.5 Higher-order finite differences
To approximate higher order derivatives, we can follow a similar reasoning. Namely, we can generalize the forward difference scheme to approximate the derivative of order by As before, we can expand the terms in the sum. For the approximation to capture only the th derivative, we now require the coefficients to satisfy With the resulting coefficients, we obtain a truncation error of order , while making evaluations. For example, for , we can approximate the second-order derivative as with a truncation error of order .
The central difference scheme can be generalized similarly by to reach truncation errors of order . For example, for , , we obtain the second-order central difference By using a Taylor expansion we see that, this time, the terms corresponding to derivatives of odd order cancel out and the truncation error is while requiring evaluations.
7.6 Complex-step derivatives
Suppose is well defined on , the space of -dimensional complex numbers. Let us denote the imaginary unit by . Then, the Taylor expansion of reads We see that the real part corresponds to even-degree terms and the imaginary part corresponds to odd-degree terms. We therefore obtain and This suggests that we can compute directional derivatives using the approximation for . This is called the complex-step derivative approximation (Martins et al., 2003; Squire and Trapp, 1998).
Contrary to forward, backward and central differences, we see that only a single function call is necessary. A function call on complex numbers may take roughly twice the cost of a function call on real numbers. However, thanks to the fact that a difference of functions is no longer needed, the complex-step derivative approximation usually enjoys smaller round-off error as illustrated in Fig. 7.1. That said, one drawback of the method is that all elementary operations within the program implementing the function must be well-defined on complex numbers, e.g., using overloading.
7.7 Complexity
We now discuss the computational complexity in terms of function evaluations of finite differences and complex-step derivatives. For concreteness, as this is the most common use case in machine learning, we discuss the case of a single output, i.e., we want to differentiate a function . Whether we use forward, backward or central differences, the computational complexity of computing the directional derivative in any direction amounts to two calls to . For computing the gradient , we can use (see Definition 2.7) that for . For forward and backward differences, we therefore need function calls to compute the gradient, while we need function calls for central differences. For the complex step approximation, we need complex function calls. We summarize the complexities in Table 7.1.
Table 7.1: Computational complexity in number of function evaluations for computing the directional derivative and the gradient of a function by finite differences and complex step derivatives.
| Directional derivative | Gradient | |
|---|---|---|
| Forward difference | ||
| Backward difference | ||
| Central difference | ||
| Complex step |
7.8 Summary
Finite differences are a simple way to numerically compute derivatives using only function evaluations.
Central differences achieve smaller truncation error than forward and backward differences. It is possible to achieve smaller truncation error, at the cost of more function evaluations.
Complex-step derivatives achieve smaller round-off error than central differences but require the function and the program implementing it to be well-defined on complex numbers.
However, whatever the method used, finite differences require a number of function calls that is proportional to the number of dimensions. They are therefore seldom used in machine learning, where there can be millions or billions of dimensions. The main use cases of finite differences are therefore i) for blackbox functions of low dimension and ii) for test purposes (e.g., checking that a gradient function is correctly implemented).
For modern machine learning, the main workhorse is automatic differentiation, as it leverages the compositional structure of functions. This is what we study in the next chapter.