In this chapter, we review duality principles in optimization.
18.1 Dual norms
We introduce in this section dual norms, since they are useful in this book.
Definition 18.1(Dual norms)
Given a norm ∥u∥, its dual is ∥v∥∗:=∥u∥≤1max⟨u,v⟩.
Therefore, the dual norm of ∥⋅∥ is the support function of the unit ball induced by the norm ∥⋅∥, B∥⋅∥:={u∈RD:∥u∥≤1}. We give examples of pairs of dual norms below.
Example 18.1(Dual norm of p-norms)
The p-norm is defined by ∥u∥p:=(j=1∑D∣uj∣p)1/p. Its dual is ∥v∥q where q is such that p1+q1=1. For instance, the dual norm of the 2-norm is itself, since 21+21=1. The 1-norm and the ∞-norm are duals of each other, since 11+∞1=1.
The definition of dual norm implies a generalization of the Cauchy–Schwarz inequality: for all u,v∈RD∣⟨u,v⟩∣≤∥u∥∗∥v∥. See, e.g., Beck (2017, Lemma 1.4).
Proposition 18.1(Conjugate of norms and squared norms)
We know that the conjugate of the support function is the indicator function. Therefore, if f(u)=∥u∥, then f∗(v)=ιB∥⋅∥(v)={0∞ if ∥v∥∗≤1 otherwise . On the other hand, if f(u)=21∥u∥2, then f∗(v)=21∥v∥∗2.
18.2 Fenchel duality
We consider in this section standard objectives of the form w∈WminL(w):=w∈Wminℓ(f(w))+R(w), where f:W→M, ℓ:M→R and R:W→R. We first show that the minimization of this objective, called the primal, can be lower bounded by a concave maximization objective, called the dual, even if the primal is nonconvex.
Proposition 18.2(Weak duality)
Let f:W→M (potentially nonlinear), ℓ:M→R (potentially nonconvex) and R:W→R (potentially nonconvex). Then w∈Wminℓ(f(w))+R(w)≥α∈Mmax−Rf(α)−ℓ∗(−α), where we used the conjugate ℓ∗(−α):=θ∈Mmax⟨−α,θ⟩−ℓ(θ) and the “generalized conjugate” Rf(α):=w∈Wmax⟨α,f(w)⟩−R(w). Moreover, ℓ∗ and Rf are both convex functions.
We emphasize that the result in Proposition 18.2 is fully general, in the sense that it does not assume the linearity of f or the convexity of ℓ and R. The caveat, of course, is that Rf and ℓ∗ are difficult to compute in general, if f is nonlinear, and if ℓ and R are nonconvex.
In the case when f(w)=Aw, where A is a linear map, and when both ℓ and R are convex, we can state a much stronger result.
Proposition 18.3(Strong duality)
Let A be a linear map from W to M. Let ℓ:M→R and R:W→R be convex functions. Let A∗ denote the adjoint of A (Section 2.3). Then, w∈Wminℓ(Aw)+R(w)=α∈Mmax−R∗(A∗α)−ℓ∗(−α). Furthermore, the primal solution satisfies w⋆∈w∈Wargmax⟨Aα⋆,w⟩−R(w). When R is strictly convex, the primal solution is uniquely determined by w⋆=∇R∗(A∗α⋆).
Proof
Since f(w)=Aw, we have Rf(α):=w∈Wmax⟨α,f(w)⟩−R(w)=w∈Wmax⟨α,Aw⟩−R(w)=w∈Wmax⟨A∗α,w⟩−R(w)=R∗(A∗α). Furthermore, the inequality in the proof of Proposition 18.2 is an equality, since the minmax is that of a convex-concave function. ◻
The maximization problem in Proposition 18.3 is called the Fenchel dual. By strong duality, the value of the maximum and the value of the minimum are equal. We can therefore choose to equivalently solve the dual instead of the primal. This can be advantageous when the space M is smaller than W.
We now apply the Fenchel dual to obtain the dual of regularized multiclass linear classification.
Example 18.2(Sum of separable loss functions)
When the loss is ℓ(θ):=∑i=1Nℓi(θi), where θ=Aw=(A1w,…,ANw)∈MN and Ai is a linear map from W to M, we obtain w∈Wmini=1∑Nℓi(Aiw)+R(w)=α∈MNmax−R∗(A∗α)−i=1∑Nℓi∗(−αi), where A∗α=(A1∗α1,…,AN∗αN). Typically, we define Aiw:=Wxi, where W∈RM×D is a reshaped version of w∈W, xi∈RD is a training sample, and M is the number of classes. In this case, we then have Ai∗αi=αixi⊤.
Examples of loss function conjugates are given in Table 18.1.
Table 18.1: Examples of loss conjugates. For regression losses (squared, absolute), where yi∈RM, we define ti=ϕ(yi)=yi. For classification losses (logistic, perceptron, hinge), where yi∈[M], we define ti=ϕ(yi)=eyi. To simplify some expressions, we defined the change of variable μi:=yi−αi.
ℓi(θi)
ℓi∗(−αi)
Squared
21∥θi−ti∥22
21∥αi∥22−⟨ti,αi⟩
Absolute
∥θi−ti∥1
ι[−1,1]M(αi)−⟨ti,αi⟩
Logistic
LSE(θi)−⟨θi,ti⟩
⟨μi,logμi⟩+ι△M(μi)
Perceptron
maxj∈[M]θi,j−θi,yi
ι△M(μi)
Hinge
maxj∈[M][j=yi]+θi,j−θi,yi
ι△M(μi)−⟨1−ti,μi⟩
18.3 Bregman divergences
Bregman divergences are a measure of difference between two points.
Definition 18.2(Bregman divergence)
The Bregman divergence generated by a differentiable convex function f:RD→R is Bf(u,v):=f(u)−f(v)−⟨∇f(v),u−v⟩=⟨∇f(v),v⟩−f(v)−[⟨∇f(v),u⟩−f(u)], where u,v∈dom(f).
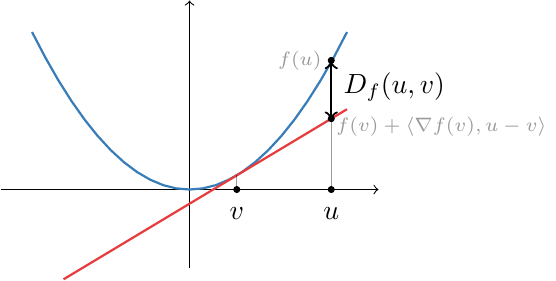
Intuitively, the Bregman divergence is the difference between f(u) and its linearization u↦f(v)+⟨∇f(v),u−v⟩ around v. This is illustrated in Fig. 18.1.
Example 18.3(Examples of Bregman divergences)
If f(u)=21∥u∥22, where dom(f)=RD, then Bf(u,v)=21∥u−v∥22, the squared Euclidean distance. If f(u)=⟨u,logu⟩, where dom(f)=R+D, then Bf(u,v)=j=1∑Dujlogvjuj−j=1∑Duj+j=1∑Dvj, the (generalized) Kullback-Leibler divergence.
Properties
Bregman divergences enjoy several useful properties.
Proposition 18.4(Properties of Bregman divergences)
Let f:RD→R be a differentiable convex function.
Non-negativity:Bf(u,v)≥0 for all u,v∈dom(f).
Positivity:Bf(u,v)=0 if and only if u=v (when f is strictly convex).
Convexity:Bf(u,v) is convex in u.
Dual-space form:Bf(u,v)=Bf∗(b,a), where b=∇f(v)∈dom(f∗) and a=∇f(u)∈dom(f∗).
Proof
The properties follow immediately from the convexity of f(u).
From the fact that u↦Bf(u,v) is the sum of f(u) and a linear function of u.
◻
Figure 18.1: The Bregman divergence generated by f is the difference between f(u) and its linearization around v.
The Bregman divergence can be used to define natural generalizations of the Euclidean projection and proximal operators, reviewed in Section 16.3 and Section 16.4.
Definition 18.3(Bregman proximal and projection operators)
Let v∈dom(f). The Bregman proximal operator is bproxf,g(v):=u∈dom(f)∩dom(g)argminBf(u,v)+g(u). In particular, the Bregman projection onto C⊆dom(f) is bprojf,C(v):=u∈CargminBf(u,v).
It turns out that these operators are intimately connected to the gradient mapping of the convex conjugate.
Proposition 18.5(Link with conjugate’s gradient)
If Ω=f+g, then for all θ∈dom(f∗)∇Ω∗(θ)=bproxf,g(∇f∗(θ)). In particular, if Ω=f+ιC, then for all θ∈dom(f∗)∇Ω∗(θ)=bprojf,C(∇f∗(θ)).
We give two examples below.
Example 18.4(Bregman projections on the simplex)
If f(u)=21∥u∥22, then bprojf,△D(v)=u∈△Dargmin21∥u−v∥22. If f(u)=⟨u,logu−1⟩, then bprojf,△D(v)=u∈△DargminKL(u,v)=softargmax(θ), where v=∇f∗(θ)=exp(θ).
Therefore, the softmax can be seen as a projection onto the probability simplex in the Kullback-Leibler divergence sense!
18.4 Fenchel-Young loss functions
We end this chapter with a brief review of the Fenchel-Young family of loss functions (Blondel et al., 2020), which includes all loss functions in Table 18.1.
Definition 18.4(Fenchel-Young loss)
The Fenchel-Young loss function generated by Ω is ℓΩ(θ,t):=Ω∗(θ)+Ω(t)−⟨θ,t⟩ where θ∈dom(Ω∗) and t∈dom(Ω).
Typically, we set θ=f(x,w), where f is a model prediction function with parameters w and t=ϕ(y), where ϕ:Y→dom(Ω). For instance, suppose we work with categorical outputs y∈[M]. Then, we can set ϕ(y)=ey, where ey is the one-hot encoding of y.
The important point to notice is that the Fenchel-Young loss is defined over arguments in mixed spaces: θ belongs to the dual space, while t belongs to the primal space. In fact, the Fenchel-Young loss is intimately connected to the Bregman divergence, since BΩ(t,v)=Ω∗(θ)+Ω(t)−⟨θ,t⟩, if we set θ=∇Ω(v). The key properties of Fenchel-Young loss functions are summarized below.
Proposition 18.6(Properties of Fenchel-Young loss functions)
Non-negativity:ℓΩ(θ,t)≥0 for all θ∈dom(Ω∗) and t∈dom(Ω).
Positivity:ℓΩ(θ,t)=0 if and only if ∇Ω∗(θ)=t, assuming Ω is strictly convex.
Convexity:ℓΩ(θ,t) is convex in θ (regardless of Ω) and in t (if Ω is convex).
Relation with composite Bregman divergence:0≤possibly nonconvex in θBΩ(t,∇Ω∗(θ))≤convex in θℓΩ(θ,t).
See Blondel et al. (2020) for an in-depth study of more properties.
18.5 Summary
The convex conjugate serves as a powerful abstraction in Fenchel duality, decoupling the dual expression and function-specific terms.
The convex conjugate is also tightly connected to Bregman divergences and can be used to derive the family of Fenchel-Young loss functions, which can be seen as primal-dual Bregman divergences.