Chapter 8Automatic differentiation
In Chapter 2, we reviewed the fundamentals of differentiation and stressed the importance of two linear maps: the Jacobian-vector product (JVP) and its adjoint, the vector-Jacobian product (VJP). In this chapter, we review forward-mode and reverse-mode autodiff using these two linear maps. We start with computation chains and then generalize to feedforward networks and general computation graphs. We also review checkpointing, reversible layers and randomized estimators.
8.1 Computation chains
To begin with, consider a computation chain (Section 4.1.1) representing a function expressed as a sequence of compositions , where . The computation of can be unrolled into a sequence of operations Our goal is to compute the variations of around a given input . In a feedforward network, this amounts to estimating the influence of a given input for fixed parameters (we will see how to estimate the variations w.r.t. parameters in the sequel).
Jacobian matrix.
We first consider the computation of the full Jacobian , seen as a matrix, as the notation indicates. Following Proposition 2.2, we have where are the Jacobians of the intermediate functions computed at , as defined in Eq. (8.1). We may also want to compute the transpose of the Jacobian In both cases, the main drawback of this approach is computational: computing the full requires materializing the intermediate Jacobians in memory and performing matrix-matrix multiplications. However, in practice, computing the full Jacobian is rarely needed. Indeed, oftentimes, we only need to right-multiply or left-multiply with . This gives rise to forward-mode and reverse-mode autodiff, respectively.
8.1.1 Forward-mode
We now interpret the Jacobian as a linear map, as the non-bold indicates. Following Proposition 2.6, is the composition of the intermediate linear maps, Evaluating on an input direction can be decomposed, like the function Eq. (8.1) itself, into intermediate computations Each intermediate amounts to a Jacobian-vector product (JVP) and can be performed in a forward manner, alongside the computation of the intermediate states . This can also be seen as multiplying the matrix defined in Eq. (8.2) with a vector, from right to left. This is illustrated in Fig. 8.1 and the procedure is summarized in Algorithm 8.1.
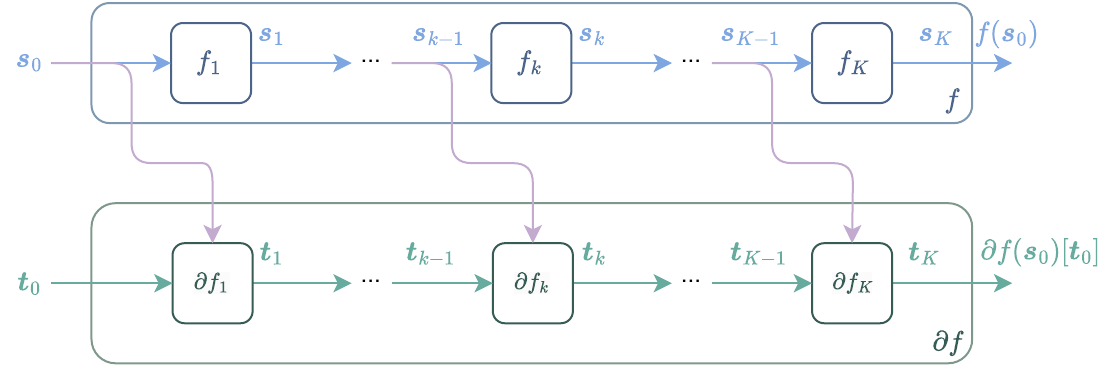
Figure 8.1: Forward-mode autodiff for a computation chain. For readability, we denoted the intermediate JVP as a function of two variables with .
Algorithm 8.1: Forward-mode autodiff for computation chains
Functions:
Inputs: input , input direction
Initialize
for do
Compute
Compute
Outputs: ,
Computational complexity.
The JVP follows exactly the computations of , with an additional variable being propagated. If we consider that computing is roughly as costly as computing , then computing a JVP has roughly twice the computational cost of . See Section 8.3.3 for a more general and more formal statement.
Memory usage.
The memory usage of a program at a given evaluation step is the number of variables that need to be stored in memory to ensure the execution of all remaining steps. The memory cost of a program is then the maximal memory usage over all evaluation steps. For our purposes, we analyze the memory usage and memory cost by examining the given program. Formal definitions of operations on memory such as read, write, delete and associated memory costs are presented by Griewank and Walther (2008, 4).
For example, to execute the chain , at each step , we only need to have access to to execute the rest of the program. As we compute , we can delete from memory and replace it by . Therefore, the memory cost associated with the evaluation of is just the maximal dimension of the variables.
For forward mode autodiff, as we follow the computations of , at each step , we only need to have access to and to execute the rest of the program. The memory used by and can directly be used for once they are computed. The memory usage associated with the JVP is summarized in Fig. 8.2. Overall the memory cost of the JVP is then exactly twice the memory cost of the function itself.
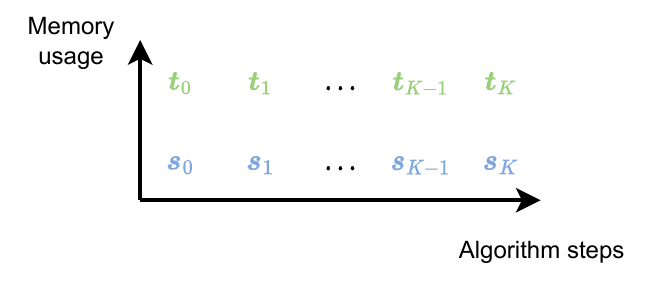
Figure 8.2: Memory usage of forward-mode autodiff for a computation chain. Here , , .
8.1.2 Reverse-mode
In machine learning, most functions whose gradient we need to compute take the form , where is a scalar-valued loss function and is a network. As seen in Proposition 2.3, the gradient takes the form This motivates the need for applying the adjoint to and more generally to any output direction . From Proposition 2.7, we have Evaluating on an output direction is decomposed as Each intermediate adjoint amounts to a vector-Jacobian product (VJP). The key difference with the forward mode is that the procedure runs backward through the chain, hence the name reverse mode autodiff. This can also be seen as multiplying Eq. (8.2) from left to right. The procedure is illustrated in Fig. 8.3 and summarized in Algorithm 8.2.
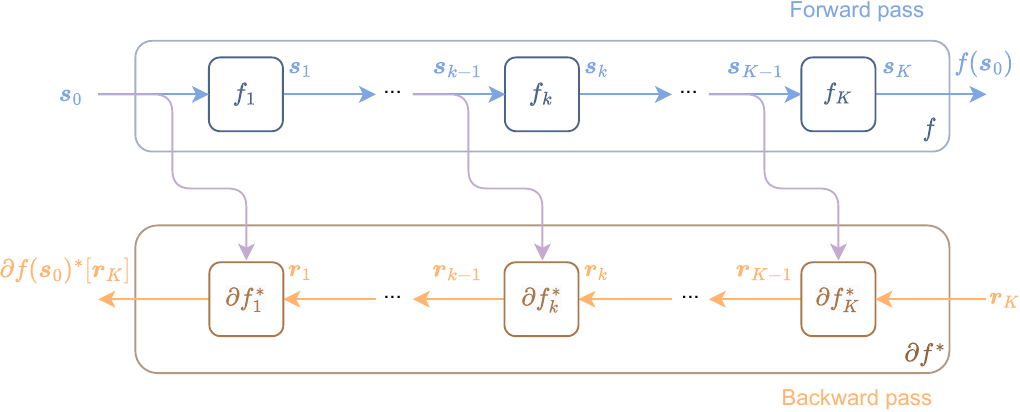
Figure 8.3: Reverse mode of automatic differentiation for a computation chain. For readability, we denoted the intermediate VJPs as functions of two variables , with .
Algorithm 8.2: Reverse-mode autodiff for computation chains
Functions: ,
Inputs: input , output direction
for do ▷ Forward pass
Compute
Initialize .
for do ▷ Backward pass
Compute
Outputs: ,
Computational complexity.
In terms of number of operations, the VJP simply passes two times through the chain, once forward, then backward. If we consider the intermediate VJPs to be roughly as costly as the intermediate functions themselves, the VJP amounts to just twice the cost of the original function, just as the JVP. See Section 8.3.3 for a more generic and formal statement.
Memory usage.
Recall that the memory usage of a program at a given evaluation step is the number of variables that need to be stored in memory to ensure the execution of the remaining steps. If we inspect Algorithm 8.3, to execute all backward steps, that is the loop in line 4, we need to have access to all the intermediate inputs . Therefore, the memory cost of reverse-mode autodiff is proportional to the length of the chain . Fig. 8.4 illustrates the memory usage during reverse mode autodiff. It grows linearly until the end of the forward pass and then progressively decreases until it outputs the value of the function and the VJP. The memory cost can be mitigated by means of checkpointing techniques presented in Section 8.5.
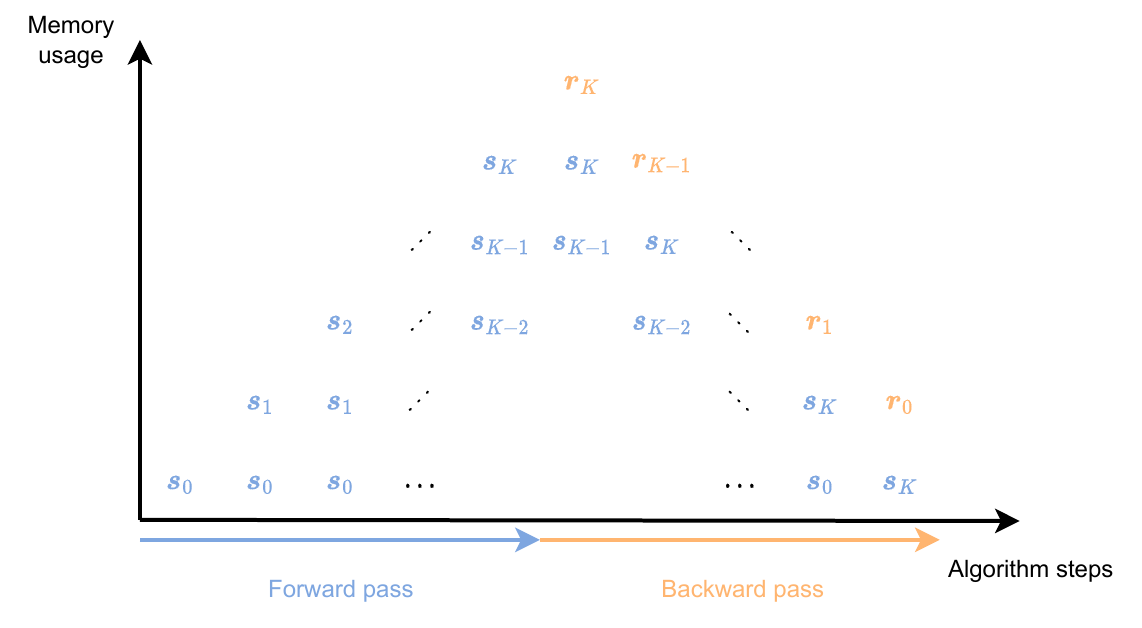
Figure 8.4: Memory usage of reverse mode autodiff for a computation chain.
Decoupled function and VJP evaluations.
The additional memory cost of reverse mode autodiff comes with some advantages. If we need to compute for different output directions , we only need to compute and store once the intermediate computations and then make calls to the backward pass. In other words, by storing in memory the intermediate computations , we may instantiate a VJP operator, which we may apply to any through the backward pass. Formally, the forward and backward passes can be decoupled as where In functional programming terminology, the VJP is a closure, as it contains the intermediate computations . The same can be done for the JVP if we want to apply it to multiple directions .
Example 8.1 (Multilayer perceptron with fixed parameters)
As a running example, consider a multilayer perceptron (MLP) with one hidden layer and (for now) given fixed weights. As presented in Chapter 4, an MLP can be decomposed as for some fixed parameters and an activation function such as the softplus activation function with derivative .
Evaluating the JVP of on an input along a direction can then be decomposed as where we used in the second line the JVP of element-wise functions as in Example 8.4.
Evaluating the VJP of at requires evaluating the intermediate VJPs at the stored activations
8.1.3 Complexity of computing entire Jacobians
In this section, we analyze the time and space complexities of forward-mode and reverse-mode autodiff for computing the entire Jacobian matrix of a computation chain , where . We assume , and . Therefore, we have and .
Complexity of forward-mode autodiff
Using Definition 2.9, we find that we can extract each column of the Jacobian matrix, for , by multiplying with the standard basis vector : Computing the full Jacobian matrix therefore requires JVPs with vectors in . Assuming each in the chain composition has the form , seen as a matrix, has size . Therefore, the computational cost of JVPs is . The memory cost is , since we can release intermediate computations after each layer is processed. Setting for simplicity and using , we obtain that the computational cost of computing JVPs and therefore of computing the full Jacobian matrix by forward-mode autodiff is . The memory cost is . If a function has a single input (), then the forward mode computes the entire Jacobian at once, which reduces to a single directional derivative.
Complexity of reverse-mode autodiff
Using Definition 2.9, we find that we can extract each row of the Jacobian matrix , for , by multiplying with the standard basis vector : Computing the full Jacobian matrix therefore requires VJPs with vectors in . Assuming as before that each in the chain composition has the form , the computational cost of VJPs is . However, the memory cost is , as we need to store the intermediate computations for each of the layers. Setting for simplicity and using , we obtain that the computational cost of computing VJPs and therefore of computing the full Jacobian matrix by reverse-mode autodiff is . The memory cost is . If the function has a single output (), reverse-mode autodiff computes the entire Jacobian at once, which reduces to the gradient.
When to use forward-mode vs. reverse-mode autodiff?
We summarize the time and space complexities in Table 8.1. Generally, if , reverse-mode is more advantageous at the price of some memory cost. If , forward mode is more advantageous.
| Forward-mode | Reverse-mode | |
|---|---|---|
| Time | ||
| Space |
Table 8.1: Time and space complexities of forward-mode and reverse-mode autodiff for computing the full Jacobian of a chain of functions , where if and . We assume is a dense linear operator. Forward mode requires JVPs. Reverse mode requires VJPs.
8.2 Feedforward networks
In the previous section, we derived forward-mode autodiff and reverse-mode autodiff for computation chains with an input . In this section, we now derive reverse-mode autodiff for feedforward networks, in which each layer is now allowed to depend explicitly on some additional parameters . The recursion is where and . Each is now a function of two arguments. The first argument depends on the previous layer, but the second argument does not. This is illustrated in Fig. 8.5. We now explain how to differentiate a feedforward network.
8.2.1 Computing the adjoint
The function has the form , where and . From Section 2.3, we know that the VJP has the form . Therefore, we want to be able to compute for any .
Fortunately, the backward recursion is only a slight modification of the computation chain case. Indeed, since , where and , the intermediate VJPs have the form . We therefore arrive at the recursion The final output is
8.2.2 Computing the gradient
We often compose a network with a loss function From Proposition 2.7, the gradient is given by where with . The output , where , corresponds to the gradient w.r.t. and is typically not needed, except in generative modeling settings. The full procedure is summarized in Algorithm 8.3.
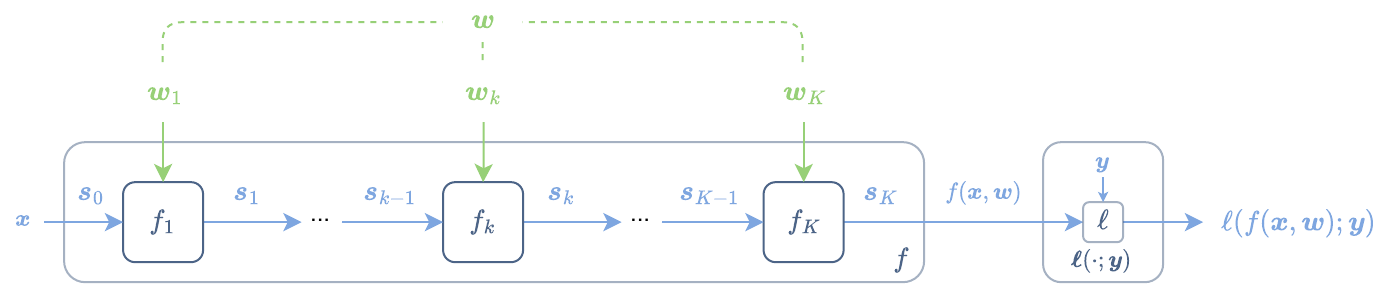
Figure 8.5: Computation graph of an MLP as a function of its parameters.
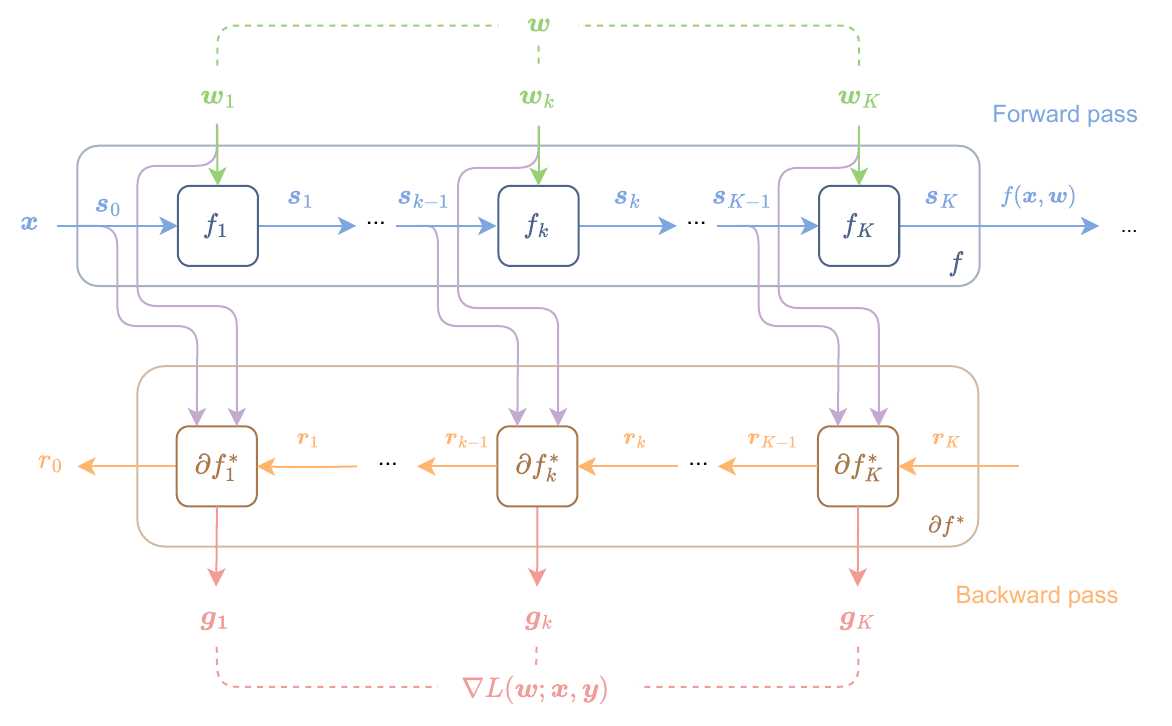
Figure 8.6: Reverse mode of automatic differentiation, a.k.a., gradient back-propagation to compute the gradient of the loss of an MLP on an input label pair. For readability, we denoted the intermediate VJPs as functions of three variables with .
Algorithm 8.3: Gradient back-propagation for feedforward networks
Functions: in sequential order
Inputs: data point
parameters
Initialize ▷ Forward pass
for do
Compute and store
Compute and
Initialize ▷ Backward pass
for do
Compute
Outputs: ,
8.3 Computation graphs
In the previous sections, we reviewed autodiff for computation chains and its extension to feedforward networks. In this section, we review its generalization to computation graphs, introduced in Section 4.1.3. Our formalism assumes, without loss of generality, that functions can take multiple inputs but only produce a single output, as we can always group multiple outputs as a tuple. This enables a one-to-one correspondence between output variables and functions .
8.3.1 Forward mode
The forward mode corresponds to computing the JVP of the program in an input direction . In the case of a computation chain , each takes a single input and each takes a single input direction . The forward pass on iteration is then, starting from , In the case of a computation graph, specified by functions in topological order, each may now take multiple inputs , and each takes as many input directions , where are the parents of . The forward pass on step then computes both intermediate inputs and directions as Let us recall that means that we differentiate w.r.t. its th argument. Using the fan-in rule in Proposition 2.8, we obtain that the derivatives are propagated as The final output is . The resulting generic forward-mode procedure is summarized in Fig. 8.7 and in Algorithm 8.4. Intuitively, the algorithm consists in computing and summing intermediate JVPs along the forward pass. Although not explicitly mentioned, we can release and from memory when no child node depends on node .
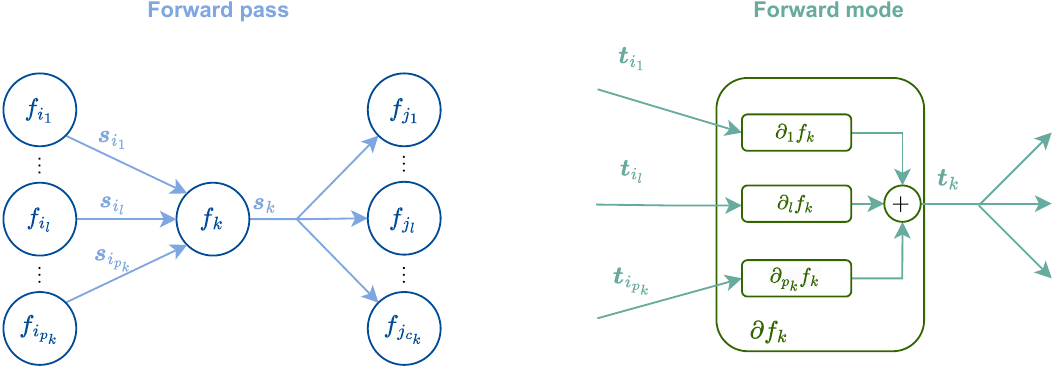
Figure 8.7: Forward mode automatic differentiation in a computation graph.
Algorithm 8.4: Forward-mode autodiff for computation graphs
Functions: in topological order
Inputs: input , input direction
Initialize
for do ▷ Forward pass
Retrieve parent nodes
Compute
Compute
Outputs: ,
8.3.2 Reverse mode
The reverse mode corresponds to computing the VJP of the program in an output direction . In the case of a computation chain , each intermediate variable is used only once to compute the next variable . To compute the VJP of the chain, it then suffices to reverse the order of the operations and to use the corresponding VJPs. Since each function takes a single input, each VJP produces a single output direction . A backward pass therefore computes from to , starting from , The final output is .
In computation graphs, intermediate variables may be used more than once, since a node may have several children nodes. This complicates reversing the computation graph. To circumvent this issue, following the formalism of Roy Frostig (Murphy, 2023, Section 6.2.2.2), we may formally distinguish between the output of and the inputs of for , the children of . We do so by introducing an operation that simply duplicates , The tuple output by is of length . The forward pass can then be formally rewritten as, for , where followed by where . The benefit of this approach is that each duplicated output is input only once to the subsequent child functions. Thanks to this, we can now associate to each variable, or , a single corresponding intermediate variable, or , in the backward pass. The reverse mode can then simply be written by going through the VJPs of the functions and the VJP of in reverse order.
For the VJP of the operation, let us denote the intermediate variables in the backward pass associated with by . Following the fan-out rule in Proposition 2.9, the VJP of the operation on iteration is In the last line, we used that by definition of the duplication operation so and . The VJP of justifies why, if an intermediate value is used by later functions , for , the derivatives with respect to need to sum all the variations through the functions into the variable .
For the VJP of the functions, following the fan-in rule in Proposition 2.8, the VJP returns multiple output variations, where , and where, for , The overall formalism is summarized in Fig. 8.8.
Implementation
The duplication operation is just a formalism to mathematically derive the reverse mode. In practice, the variables are not duplicated but accessed several times during the backward pass. The variables are computed by accumulating into each time a variable is computed. Therefore, for each , we can compute the VJP and perform the in-place updates, The topological ordering ensures that has been fully computed when we reach . The resulting generic reverse-mode procedure is presented in Algorithm 8.5.
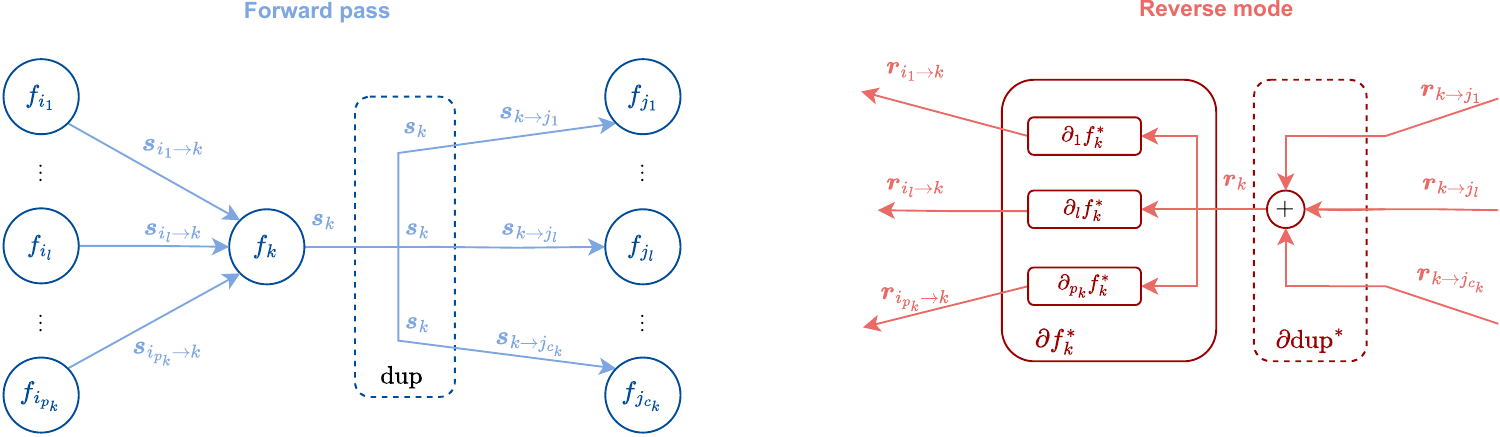
Figure 8.8: Reverse mode automatic differentiation in a computation graph.
Algorithm 8.5: Reverse-mode autodiff for computation graphs
Functions: in topological order
Inputs: input , output direction
for do ▷ Forward pass
Retrieve parent nodes
Compute
Instantiate VJP
Initialize , ▷ Backward pass
for do
Retrieve parent nodes
Compute
Compute
Outputs: ,
Example 8.2 (Example of forward and reverse modes)
We use Fig. 8.9 to illustrate the forward and reverse modes in a computation graph. Let us assume that the intermediate variables have readily been computed. The forward mode corresponds to The reverse mode corresponds to
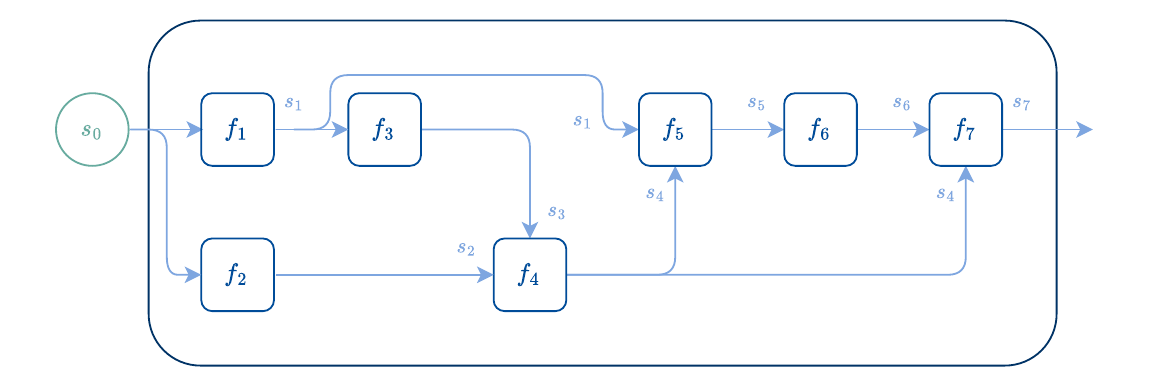
Figure 8.9: Same computation graph as Fig. 4.3 but without the actual definition of each , for simplicity.
8.3.3 Complexity, the Baur-Strassen theorem
For computing the gradient of a function represented by a computation graph, we saw that the reverse mode is more efficient than the forward mode. As we previously stated, assuming that the elementary functions in the DAG and their VJP have roughly the same computational complexity, then and have roughly the same computational complexity. This fact is crucial and is the pillar on which modern machine learning relies: it allows us to optimize high-dimensional functions by gradient descent.
For arithmetic circuits, reviewed in Section 4.1.4, this crucial fact is made more precise in the celebrated Baur-Strassen theorem (Baur and Strassen, 1983). If is a polynomial, then so is its gradient . The theorem gives an upper bound on the size of the best circuit for computing from the size of the best circuit for computing .
Proposition 8.1 (Baur-Strassen’s theorem)
For any polynomial
, we have where the size of a polynomial is defined in Definition 4.1.
A simpler proof by backward induction was given by Morgenstern (1985). See also the proof of Theorem 9.10 in Chen et al. (2011). For general computation graphs, that have more primitive functions than just and , a similar result can be obtained; see, e.g., (Bolte et al., 2022, Theorem 2).
8.4 Implementation
8.4.1 Primitive functions
An autodiff system implements a set of primitive or elementary functions, which serve as building blocks for creating other functions, by function composition. For instance, we saw that in arithmetic circuits (Section 4.1.4), . More generally, may contain all the necessary functions for expressing programs. We emphasize, however, that is not necessarily restricted to low-level functions such as log and exp, but may also contain higher-level functions. For instance, even though the log-sum-exp can be expressed as the composition of elementary operations (log, sum, exp), it is usually included as a primitive on its own, both because it is a very commonly-used building block, but also for numerical stability reasons.
8.4.2 Closure under function composition
Each function in a computation graph belongs to a set , the class of functions supported by the system. A desirable property of an autodiff implementation is that the set is closed under function composition, meaning that if and , then . This means that composed functions can themselves be used for composing new functions. This property is also crucial for supporting higher-order differentiation (Chapter 9) and automatic linear transposition (Section 8.4.4). When is a composition of elementary functions in , then itself is a nested DAG. However, we can always inline each composite function, such that all functions in the DAG belong to .
8.4.3 Examples of JVPs and VJPs
An autodiff system must implement for each its JVP for supporting the forward mode, and its VJP for supporting the reverse mode. We give a couple of examples. We start with the JVP and VJP of linear functions.
Example 8.3 (JVP and VJP of linear functions)
Consider the matrix-vector product , where is fixed and . As already mentioned in Section 2.3.1, the JVP of at along an input direction is simply To find the associated VJP, we note that for any and , we must have . Using the properties of the trace, we have Therefore, we find that the VJP is given by Similarly, consider now a matrix-matrix product , where and where is fixed. The JVP at along an input direction is simply The VJP along the output direction is
Another simple example is element-wise separable functions.
Example 8.4 (JVP and VJP of separable function)
Consider the function , where each has a derivative . The Jacobian matrix is then a diagonal matrix In this case, the JVP and VJP are actually the same where indicates element-wise multiplication.
8.4.4 Automatic linear transposition
On first sight, if we want to support both forward and reverse modes, it appears like we need to implement both the JVP and the VJP for each primitive operation . Fortunately, there exists a way to recover VJPs from JVPs, and vice-versa.
We saw in Section 2.3 that if is a linear map, then its JVP is (independent of ). Conversely, the VJP is , where is the adjoint operator of (again, independent of ).
Let us define , i.e., the VJP of in the output direction . Since is linear in , we can apply the reasoning above to compute its VJP which is independent of . In words, the VJP of a VJP is the corresponding JVP! This means that we can implement forward-mode autodiff even if we only have access to VJPs. As an illustration and sanity check, we give the following example.
Example 8.5 (Automatic transpose of “dot”)
If we define
, from Example 8.3, we know that Using Proposition 2.9, we obtain
The other direction, automatically creating a VJP from a JVP, is also possible but is more technical and relies on the notion of partial evaluation (Frostig et al., 2021; Radul et al., 2022).
8.5 Checkpointing
We saw that forward-mode autodiff can release intermediate computations from memory along the way, while reverse-mode autodiff needs to cache all of them. This means that the memory complexity of reverse-mode autodiff, in its standard form, grows linearly with the number of nodes in the computation graph. A commonly-used technique to circumvent this issue is checkpointing, which trades-off computation time for better memory usage. Checkpointing works by selectively storing only a subset of the intermediate values, called checkpoints, and by recomputing others on the fly. The specific choice of the checkpoint locations in the computation graph determines the memory-computation trade-off. While it is possible to heuristically set checkpoints at user-specified locations, it is also possible to perform a checkpointing strategy algorithmically, as studied in depth by Griewank (1992; Griewank and Walther, 2008). In this section, we review two divide-and-conquer algorithms: recursive halving and dynamic programming. Our exposition focuses on computation chains , with for simplicity.
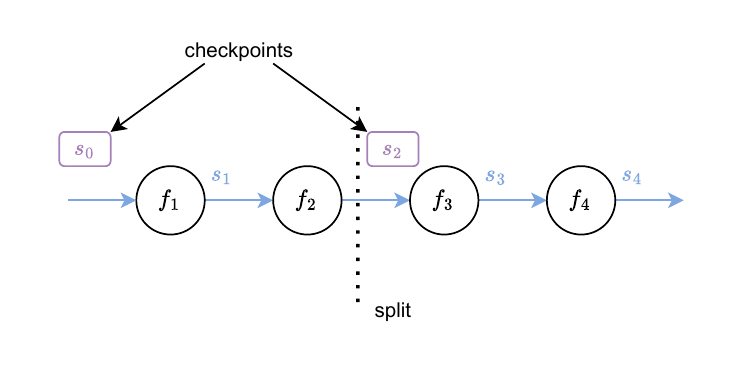
Figure 8.10: Checkpointing trades-off computation time for better memory usage by selectively storing only a subset of the intermediate values, called checkpoints, and by recomputing others on the fly. Recursive halving and dynamic programming are two divide-and-conquer strategies to select the checkpoint locations.
Computational and memory complexities at two extremes.
Let be the number of calls to the individual functions (we ignore the cost of computing the intermediate VJPs) and be the number of function inputs cached, when performing reverse-mode autodiff on a chain . On one extreme, if we store all intermediate computations, as done in Algorithm 8.2, to compute only the VJP , we have This is optimal w.r.t. computational complexity, but suboptimal w.r.t. memory. On the other extreme, if we only store the initial input, as done in Algorithm 8.6, then we have This is optimal w.r.t. memory but leads to a computational complexity that is quadratic in .
Algorithm 8.6: Reverse-mode autodiff with constant memory
Inputs: Chain , input , output direction
if then
return
else
Set
for do
Compute
Compute
return:
8.5.1 Recursive halving
As a first step towards obtaining a better computation-memory trade-off, we may split the chain as for even. Then, rather than recomputing all intermediate computations from the input as in Algorithm 8.6, we can store and recompute for starting from . Formally, this strategy amounts to the following steps.
Compute
Compute
Compute
At the expense of having to store the additional checkpoint , this already roughly halves the computational complexity compared to Algorithm 8.6.
Algorithm 8.7: Reverse-mode autodiff with recursive halving
Functions: Chain
Inputs: input , output direction
if then
return
else
Compute
Compute
Compute
return:
We can then apply this reasoning recursively, as formalized in Algorithm 8.7. The algorithm is known as recursive binary schedule (Griewank, 2003) and illustrated in Fig. 8.11. In terms of number of function evaluations , for even, we make function calls, and we call the procedure recursively twice, that is, If the chain is of length , we directly use the VJP, so . Hence, the number of function calls, if is a power of , is In terms of memory usage, Algorithm 8.7 uses not only at line 4 but also at line 6. So when the algorithm is called recursively on the second half of the chain at line 5, one memory slot is taken by . This line is called recursively until the chain is reduced to a single function. At that point, the total number of memory slots used is equal to the number of times we split the function in half, that is, for a power of . On the other hand, the input is no longer used after line 6 of Algorithm 8.7. At that line, the memory slot taken by can be consumed by the recursive call on the first-half. In other words, calling the algorithm recursively on the first half does not incur extra memory cost. So if is a power of , the memory cost of Algorithm 8.7 is
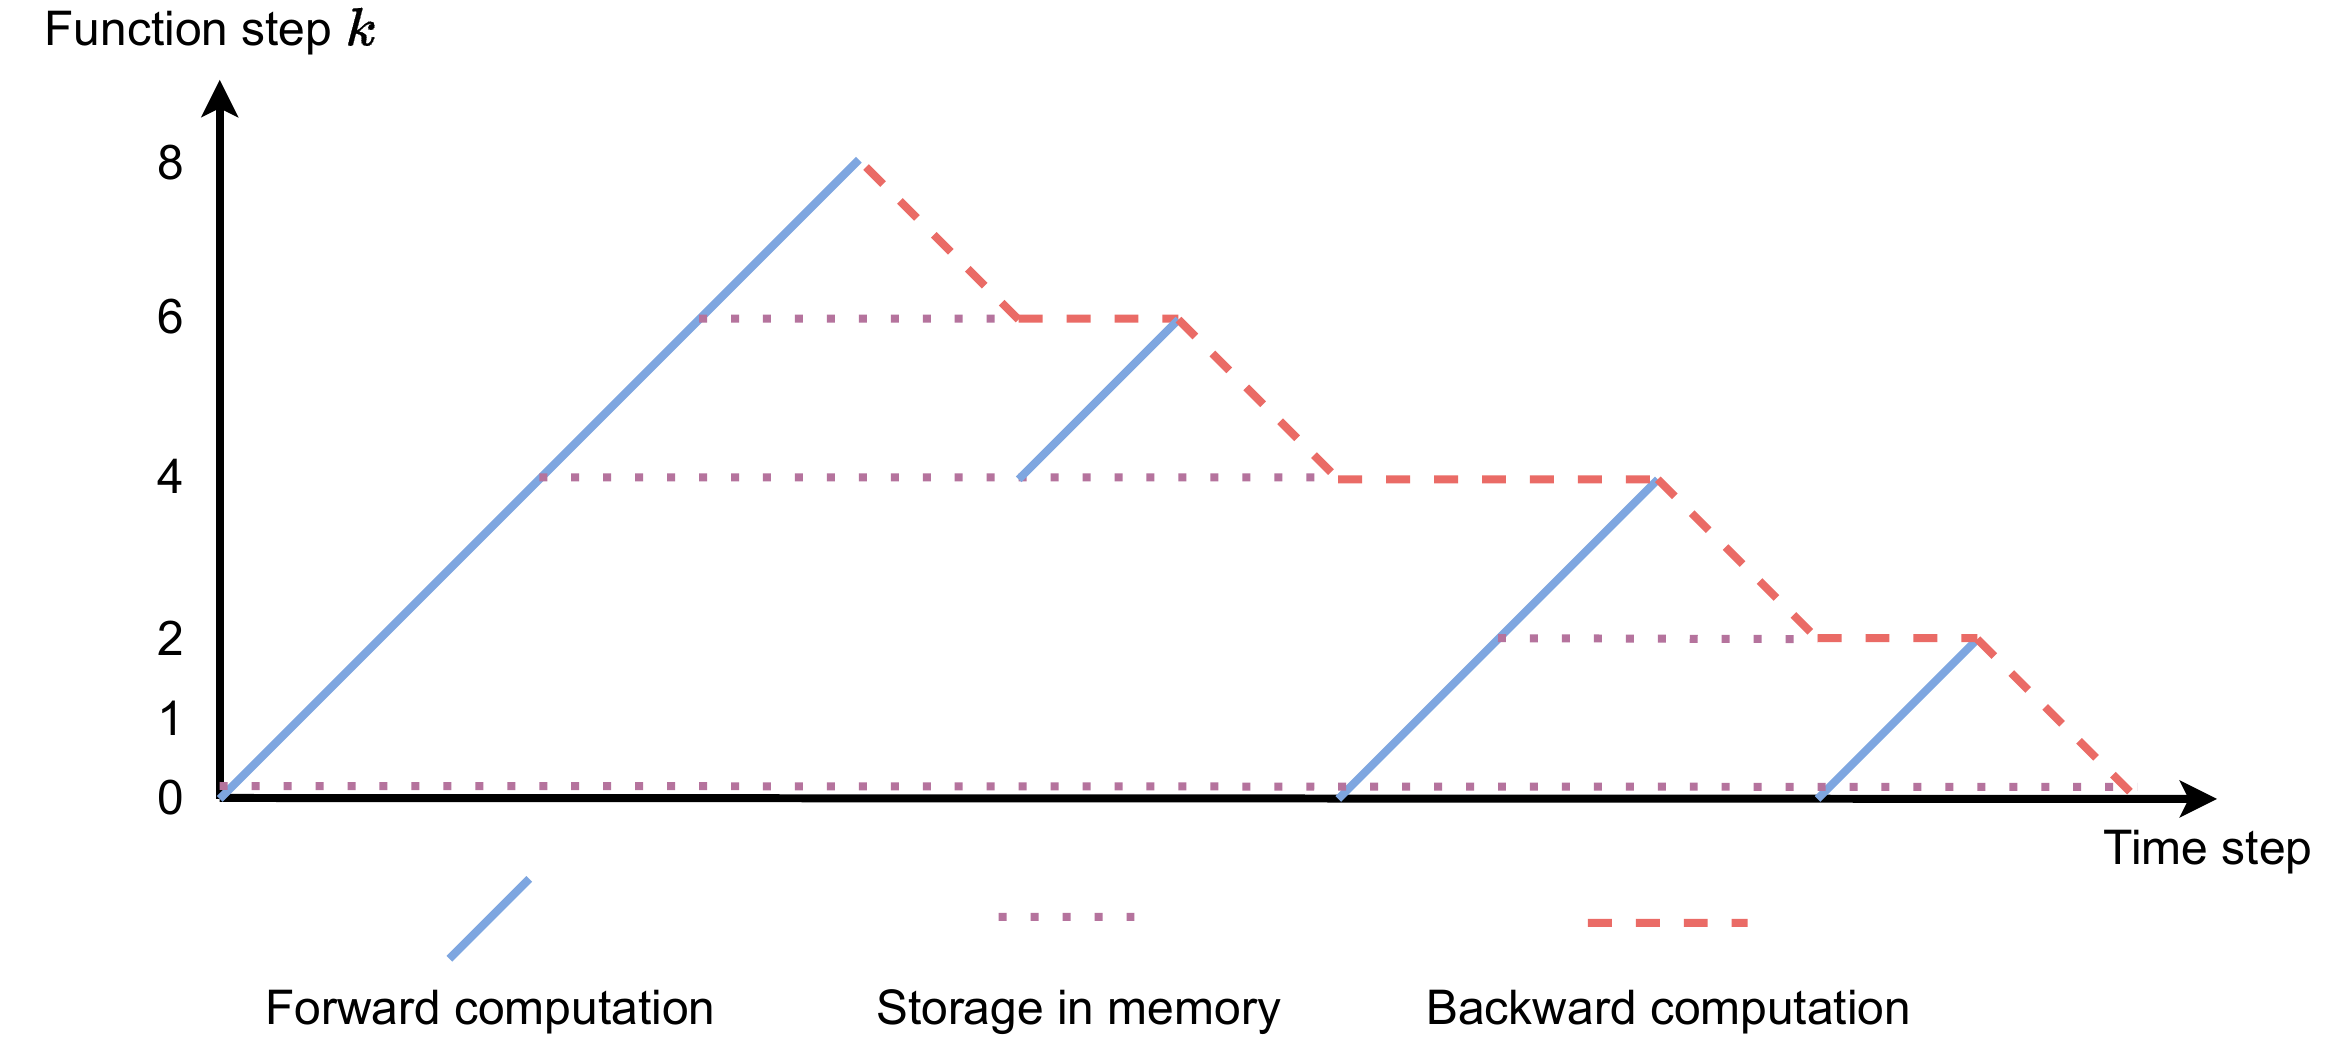
Figure 8.11: Illustration of checkpointing with recursive halving, for a chain of functions. The chain is first fully evaluated while storing some computations as checkpoints in memory. Then, during the backward pass, we recompute some intermediate values from the latest checkpoint available. In contrast, vanilla reverse-mode autodiff (with full caching of the intermediate computations) would lead to a simple triangle shape.
8.5.2 Dynamic programming
Recursive halving requires memory slots for a chain of length . However, as illustrated in Fig. 8.11, at a given time step, all memory slots may not be exploited.
To optimize the approach, we observe that recursive halving is just one instance of a program that splits the chain and calls itself recursively on each part. In other words, it is a form of divide-and-conquer algorithm. Rather than splitting the chain in half, we may consider splitting the chain at some index . One split is used to reverse the computations from to by a recursive call that consumes one memory slot. The other split is used on a recursive call that reverses the computations from to . That second call does not require an additional memory slot, as it can use directly the memory slot used by the original input . To split the chain in such two parts, we need intermediate computations to go from to . The computational complexity , counted as the number of function evaluations, for a chain of length with memory slots then satisfies the recurrence for all . By simply taking , we recover exactly the computational complexity of recursive halving. To refine the latter, we may split the chain by selecting to minimize the complexity. An optimal scheme must satisfy the recursive equation, Note that can be computed from for , . This suggests a dynamic programming approach to find an optimal scheme algorithmically. For a chain of length , the cost is null as we directly reverse the computation, so . On the other hand for a memory , there is only one possible scheme that saves only the initial input as in Algorithm 8.6, so . The values can then be computed incrementally from to and to using Eq. (8.3). The optimal splits can be recorded along the way as The optimal split for can then be found by backtracking the optimal splits along both branches corresponding to and . As the final output consists in traversing a binary tree, it was called treeverse (Griewank, 1992). Note that the dynamic programming procedure is generic and could a priori incorporate varying computational costs for the intermediate functions .
Analytical formula
It turns out that we can also find an optimal scheme analytically. This scheme was found by Griewank (1992), following the analysis of optimal inversions of sequential programs by divide-and-conquer algorithms done by Grimm et al. (1996); see also Griewank (2003, Section 6) for a simple proof. The main idea consists in considering the number of times an evaluation step is repeated. As we split the chain at , all steps from to will be repeated at least once. In other words, treating the second half of the chain incurs one memory cost, while treating the first half of the chain incurs one repetition cost. Griewank (1992) shows that for fixed , , we can find the minimal number of repetitions analytically and build the corresponding scheme with simple formulas for the optimal splits.
Compared to the dynamic programming approach, it means that we do not need to compute the pointers , and we can use a simple formula to set . We still need to traverse the corresponding binary tree given and to obtain the schedules. Note that such an optimal scheme does not take into account varying computational costs for the functions .
8.5.3 Online checkpointing
The optimal scheme presented above requires knowing the total number of nodes in the computation graph ahead of time. However, when differentiating through for example a while loop (Section 5.10), this is not the case. To circumvent this issue, online checkpointing schemes have been developed and proven to be nearly optimal (Stumm and Walther, 2010; Wang et al., 2009). These schemes start by defining a set of checkpoints with the first computations, then these checkpoints are rewritten dynamically as the computations keep going. Once the computations terminate, the optimal approach presented above for a fixed length is applied on the set of checkpoints recorded.
8.6 Reversible layers
8.6.1 General case
The memory requirements of reverse-mode autodiff can be completely alleviated when the functions are invertible (meaning that exists) and when is easily accessible. In that case, rather than storing the intermediate computations , necessary to compute the VJP , one can compute them on the fly during the backward pass from using . We summarize the procedure for the case of computation chains in Algorithm 8.8. Compared to vanilla reverse-mode autodiff in Algorithm 8.2, the algorithm has optimal memory complexity, as we can release and as we go.
Algorithm 8.8: Reverse-mode autodiff for reversible chains.
Functions: , with each invertible
Inputs: input , output direction
Compute
for do
Compute
Compute
Outputs: ,
In practice, often does not exist or may not be easily accessible. However, network architectures can be constructed to be easily invertible by design. Examples include reversible residual networks (Gomez et al., 2017), orthonormal RNNs (Helfrich et al., 2018), neural ODEs (Section 12.6), and momentum residual neural networks (Sander et al., 2021a); see also references therein.
8.6.2 Case of orthonormal JVPs
When the JVP of each is an orthonormal linear mapping, i.e., it is easy to check that the VJP of is equal to the JVP of , that is In other words, in the case of orthonormal JVPs, reverse-mode autodiff of coincides with forward-mode autodiff of !
8.7 Randomized forward-mode gradient estimator
Forward-mode autodiff does not require storing intermediate activations. However, for a function , computing the gradient using forward-mode autodiff requires JVPs, which is intractable if is large. Can we approximate with fewer JVPs? The following proposition gives an unbiased estimator of that only involves JVPs.
Proposition 8.2 (Unbiased forward-mode estimator of the gradient)
Let be a differentiable function. Then, where is the isotropic Gaussian distribution.
This estimator is for instance used by Baydin et al. (2022). It can be seen as the zero-temperature limit of the gradient of a perturbed function, estimated by the score-function estimator (SFE); see Section 14.4.6.
In practice, the expectation above can be approximated by drawing noise vectors , and averaging over .
A word of caution: while this estimator can be useful for example when we do not want to store the intermediate activations for memory reasons, this of course comes at the cost of increasing the variance, which influences the convergence rate of SGD, as seen in Section 16.2.
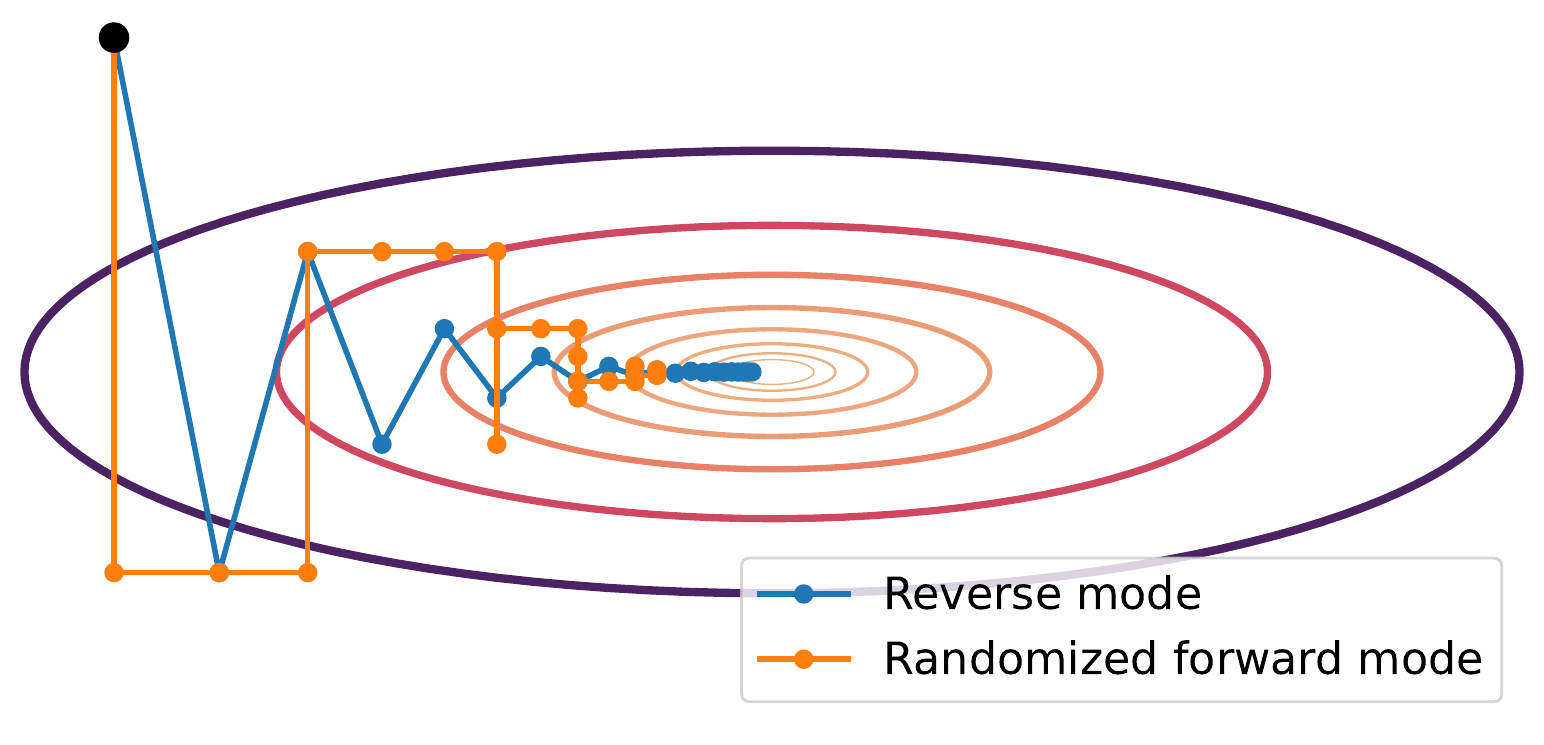
Figure 8.12: The randomized forward-mode gradient estimator only requires forward passes, but it suffers from high variance, even more so in high dimension.
8.8 Summary
Computer programs can be seen as directed acyclic graphs, where nodes correspond to the output of intermediate operations in the program, and edges represent the dependencies of current operations on past operations.
Automatic differentiation (autodiff) for a function has two main modes: forward mode and reverse mode.
The forward mode: i) uses JVPs, ii) builds the Jacobian one column at a time, iii) is efficient for tall Jacobians (), iv) need not store intermediate computations.
The reverse mode: i) uses VJPs, ii) builds the Jacobian one row at a time, iii) is efficient for wide Jacobians (), iv) needs to store intermediate computations, in order to be computationally optimal.
To trade computational efficiency for better memory efficiency, we can use checkpointing techniques.
The complexity of computing the gradient of a function using the reverse mode is at most a constant time bigger than that of evaluating the function itself. This is the Baur-Strassen theorem, in arithmetic circuits. This astonishing result is one of the pillars of modern machine learning.