Chapter 16First-order optimization
16.1 Gradient descent
Gradient descent is one of the simplest algorithms in our toolbox to minimize a function. At each iteration, it moves along the negative gradient direction, scaled by a stepsize : The path taken by a gradient descent on a simple quadratic is illustrated in Fig. 16.1 for different choices of the stepsize.
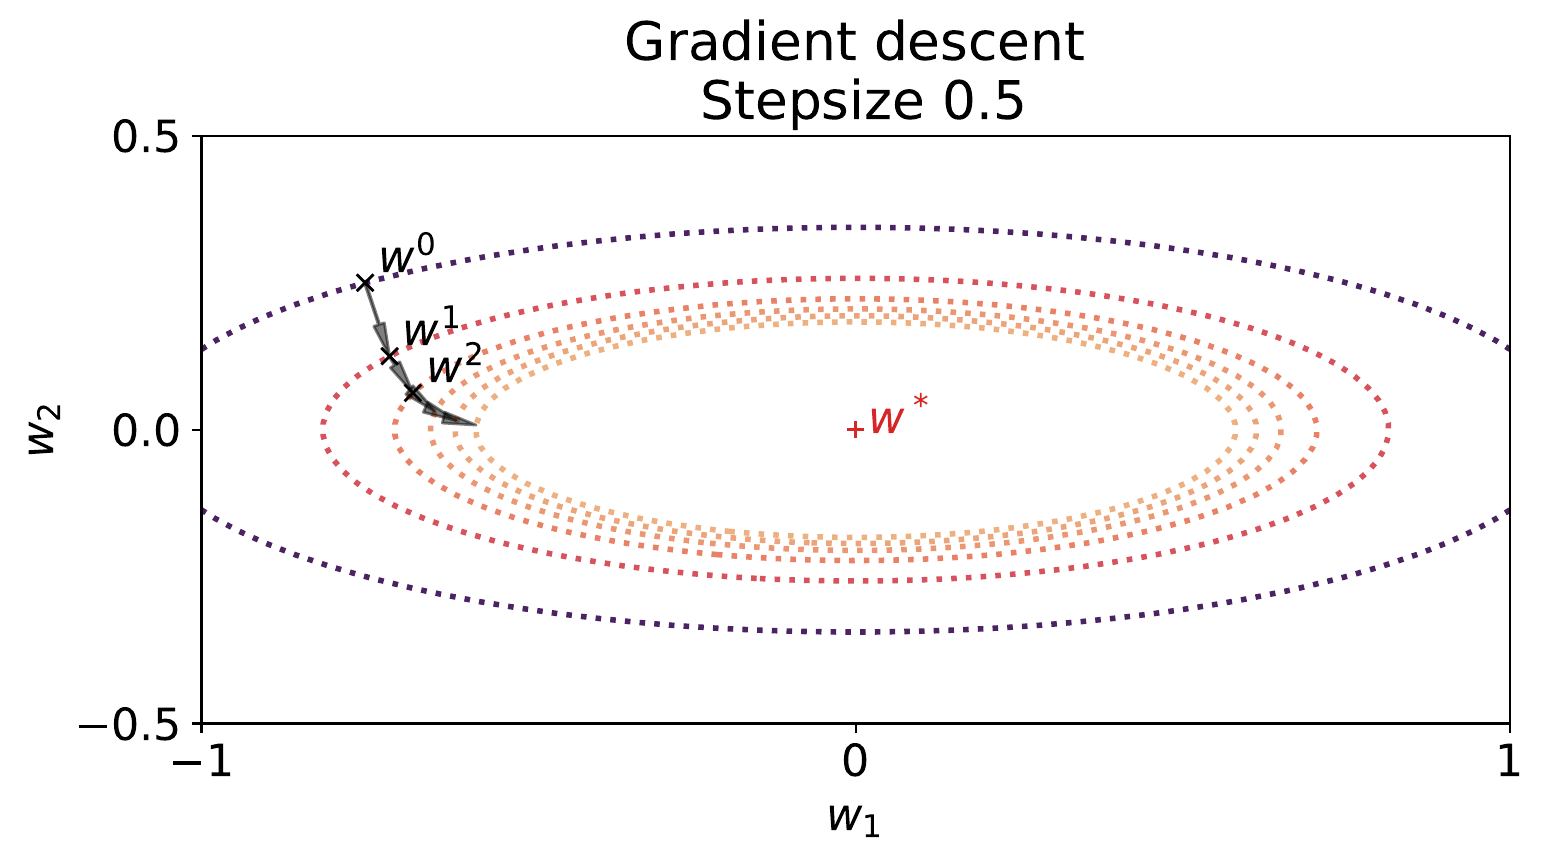
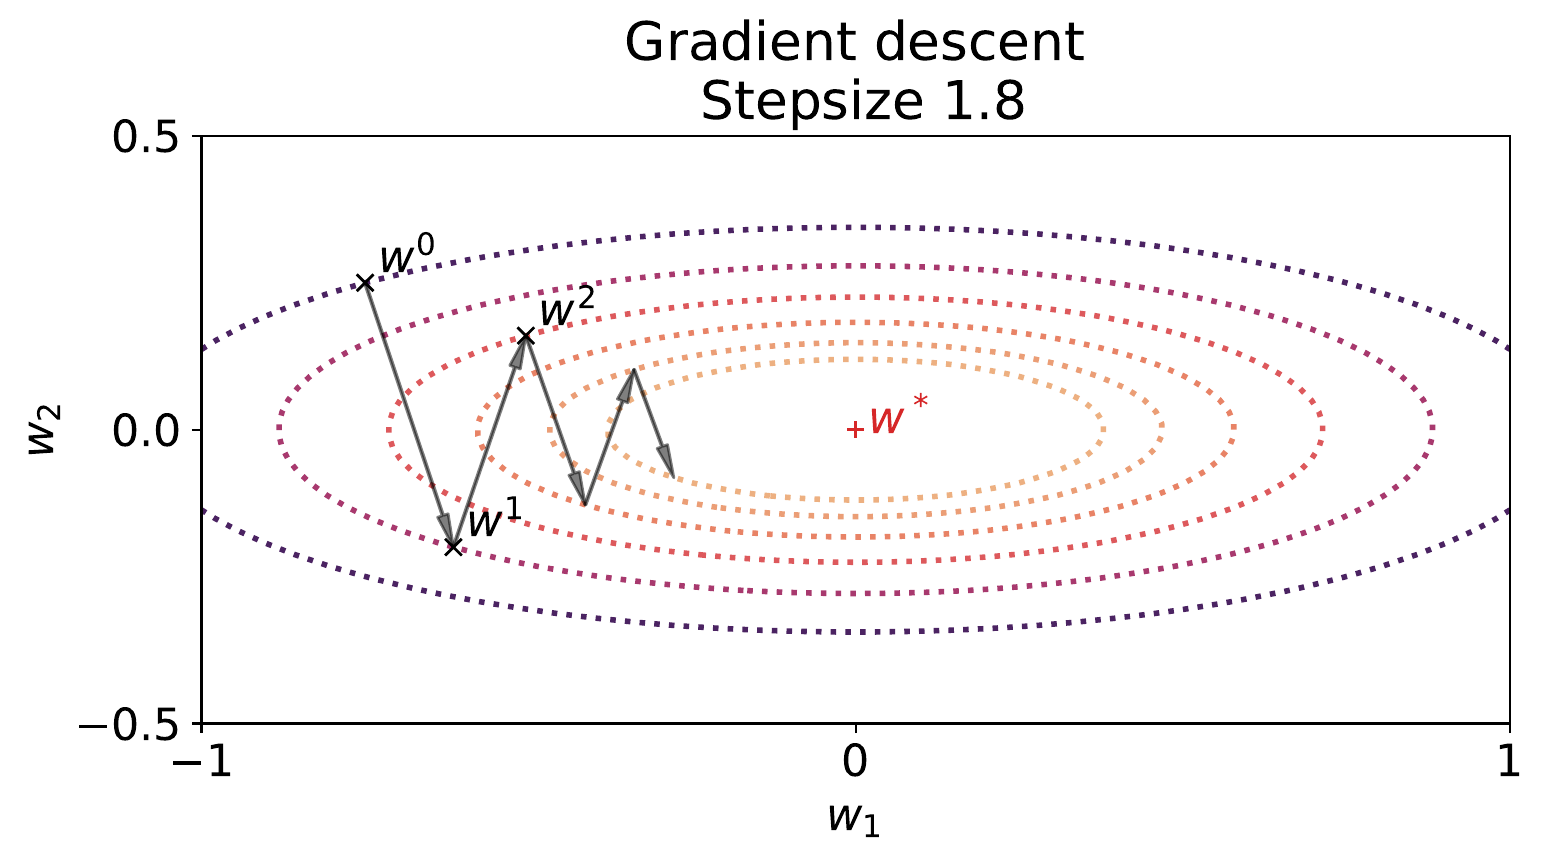
Figure 16.1: Trajectory taken by gradient descent on the objective with a small (left) or large (right) stepsize. In each case, the iterates follow the normal vectors to the contour lines (dashed lines): the negative gradients. A small stepsize leads to slow convergence but a larger stepsize induces oscillations.
16.1.1 Variational perspective
Consider the linear approximation of around , One can easily check that the gradient descent update in Eq. (16.1) can be rewritten as the solution of a minimization problem, namely, In words, a gradient descent update optimizes a trade-off between staying close to the current , thanks to the proximity term , and minimizing the linearization of around . Intuitively, by choosing sufficiently small, we ensure that the minimizer of the regularized linear approximation stays in a neighborhood where the linear approximation is valid. This viewpoint is useful to motivate gradient descent extensions.
16.1.2 Convergence for smooth functions
As long as , the function has a negative derivative at 0, i.e., . Hence, as long as , there exists a stepsize ensuring a decrease in objective values at each iterate. However, without further assumptions, such a stepsize may depend on each iterate and may be infinitesimally small. To quantify the convergence of gradient descent with a constant stepsize, we restrict to the class of smooth functions. By applying Proposition 15.1 on the iterate of gradient descent, we obtain that Therefore, for -smooth functions, by selecting , we get that which illustrates the main mechanism behind gradient descent: each iteration decreases the objective by a constant times the norm of the gradient of the current iterate. This equation can further be summed over all iterates up to . This telescopes the objective values, leading to where we recall that is the infimum of . Therefore, after sufficiently many iterations, gradient descent finds a point whose gradient norm is arbitrarily small.
Non-convex case
Without further assumptions, i.e., in the non-convex case, the above result (i.e., convergence to a stationary point, measured by the gradient norm) is the best we may get in theory. Denoting the number of iterations needed for a gradient descent to output a point that is -stationary, i.e., , we have .
Convex case
By adding a convexity assumption on the objective, we can use the lower bound provided by the convexity assumption to ensure convergence to a minimum. Namely, for a -smooth and convex function , and with stepsize , we have that (Nesterov, 2018) That is, we get a sublinear convergence rate, and the associated computational complexity to find a minimum is .
Strongly convex case
If we further strengthen the assumptions by considering -smooth, -strongly convex functions, the convergence rate of a gradient descent can be shown to be (Nesterov, 2018), for any stepsize , That is, we obtain a linear convergence rate and the associated computational complexity is . The above convergence rates may be further refined (Nesterov, 2018); we focused above on the simplest result for clarity.
Strong convexity can also be replaced by a weaker assumption, gradient-dominating property (Polyak, 1963), i.e., for some constant and any . A convex, gradient-dominating function can also be minimized at a linear rate.
16.1.3 Momentum and accelerated variants
We started with gradient descent as a simple example of first-order optimization algorithm. However, different optimization algorithms can be designed from the access to first-order oracles and the knowledge of the class of functions considered. For example, consider quadratic convex functions , that are a basic example of smooth strongly convex functions if is positive definite. An optimal method in this case is the heavy-ball method of Polyak (1964), that can be written as The heavy-ball method uses an additional variable , that can be interpreted as the velocity of a ball driven by the negative gradient to converge towards a minimum. Intuitively, this additional velocity circumvents the oscillations that a gradient descent may present as illustrated in Fig. 16.2 compared to Fig. 16.1. For , we recover usual gradient descent. For , the velocities accumulate a form of an inertia momentum, where is interpreted as the “mass” of the ball. In terms of convergence rates, the heavy-ball method can be shown to converge linearly similarly to gradient descent, but with a rate for appropriate choices of . In comparison, by choosing an optimal stepsize for the gradient descent, its convergence rate is which is provably worse, as we always have .
Beyond the case of quadratic functions, accelerated variants of gradient descent for convex or strongly convex functions have been developed by Nesterov (2018). Such variants have inspired the design of optimization algorithms in stochastic settings presented below.
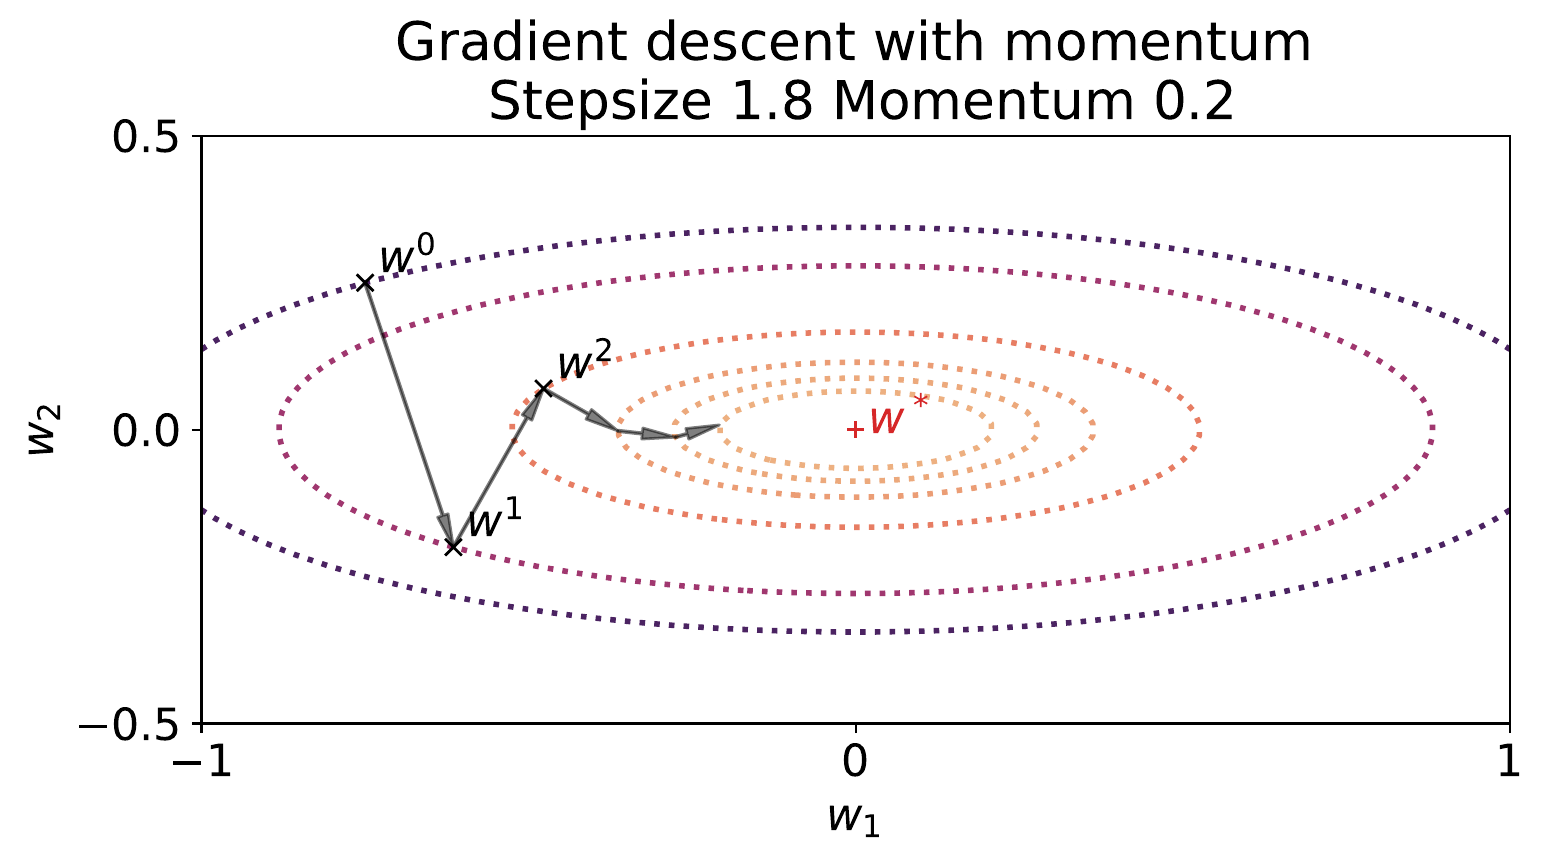
Figure 16.2: Trajectory taken by gradient descent with momentum. Compared to gradient descent without momentum, for the same stepsize, the oscillations previously observed in Fig. 16.1 are no longer present, and the algorithm converges faster to the minimum.
16.2 Stochastic gradient descent
In machine learning, we are usually interested in minimizing the expected loss of the model over the data distribution : For example, is often set to , where is a loss function, is a neural network and is a random pair, composed of an input and an associated target , sampled from . In this setting, since the data distribution is generally unknown and may be infinite, we cannot exactly evaluate the expected loss or its gradient .
In practice, we are often given a fixed dataset of pairs . This is a special case of the expected loss setting, since this can be seen as an empirical distribution The gradient of is then In this case, we see that the full gradient , as needed by gradient descent, is the average of the individual gradients. That is, the cost of computing is proportional to the number of training points . For very large, that is a very large amount of samples, this computational cost can be prohibitive. Stochastic gradients circumvent this issue.
16.2.1 Stochastic gradients
Usually, even if we do not know , we can sample from it, i.e., we have access to samples . We can then use a stochastic gradient of the form as a random estimate of . This may look like a rough estimate but, on average, this is a valid approximation since We say that is an unbiased estimator of . To further improve the approximation, we may also consider mini-batch estimates by sampling data points and using , whose expectation still matches , while potentially reducing the approximation error by averaging multiple stochastic gradients. Computationally, the main advantage is that the cost is now proportional to instead of .
In whole generality, one can consider stochastic first-order oracles defined below.
Definition 16.1 (Stochastic first-order oracles)
A stochastic first-order oracle of an expected objective is a random estimate of with sampled according to some distribution . A stochastic gradient is said to be an unbiased estimator if The variance of a stochastic gradient is
When , we recover stochastic gradients. When is the product of independent samples according to , we recover mini-batch stochastic gradients. First-order stochastic optimization algorithms build upon stochastic first-order oracles to approximately find the minimum of the expected objective. In such a setting, the iterates of the algorithm are by definition random. Convergence rates therefore need to be expressed in probabilistic terms by considering for example the expected objective value according to the randomness of the oracles.
16.2.2 Vanilla SGD
Equipped with a stochastic first-order oracle, such as (mini-batch) stochastic gradients, we can define stochastic gradient descent as We assume that is independent of . Compared to the usual gradient descent, the main impediment of the stochastic setting is the additional noise induced by the stochastic estimates: their variance.
For example, consider applying a stochastic gradient descent on the expectation of -smooth convex functions with unbiased oracles. To harness the randomness of the iterates, consider after iterations outputting the average of the first iterates, that is . Moreover, suppose that the variance of the stochastic first-order oracles is bounded by for all minimizers of . Denoting by the randomness associated to the stochastic oracles, we have then that for a stepsize (Lan, 2012), The resulting convergence rate illustrates that a stochastic gradient descent converges to the minimum of the expected objective up to a constant term depending on the variance of the oracle and the stepsize. One can diminish the variance by considering mini-batches: if the variance of a single stochastic gradient is , considering a mini-batch of gradients reduces the variance of the corresponding oracle to . To decrease the additional term, one may also decrease the stepsizes over the iterations. For example, by choosing a decreasing stepsize like , the convergence rate is then of the order . The stepsize can also be selected as a constant that decreases the average objective for the first iterations and is reduced by a multiplicative factor at regular intervals like for to handle iterations between . Alternative stepsize schedules such as a cosine decay (Loshchilov and Hutter, 2016) have recently become popular.
The literature on alternative optimization schemes for stochastic optimization is still rapidly evolving, with new heuristics regularly proposed. We present below two popular techniques.
16.2.3 Momentum variants
Accelerated optimization algorithms developed in the deterministic setting may be extended to the stochastic setting. For example, the heavy-ball method can be adapted to the stochastic setting, leading to stochastic gradient descent with momentum (Sutskever et al., 2013) generally implemented as As mentioned earlier the momentum method can be modified to handle non-quadratic smooth strongly convex functions. This leads to Nesterov’s accelerated method in the deterministic setting. This has been adapted to the stochastic setting with a so-called Nesterov momentum (Sutskever et al., 2013)
16.2.4 Adaptive variants
In any gradient descent-like algorithm, selecting the stepsize is key for good performance. While a constant stepsize may be used if the function is smooth, we may not know in advance the smoothness constant of the objective, which means that additional procedures may be required to select appropriately the stepsize. In the deterministic case, line-searches such as the Armijo or Wolfe’s rules (Wright and Nocedal, 1999) can be used to check whether the selected stepsize sufficiently decreases the objective at each iteration. Such rules have been adapted in the stochastic setting (Vaswani et al., 2019).
Another way to decrease the sensitivity of the algorithm with respect to the stepsize has been to estimate first- and second-order moments of the gradients and use the latter as a form of preconditioning to smooth the trajectory of the iterates. This led to the popular Adam optimizer (Kingma and Ba, 2014). It takes the form, where , denotes the element-wise square of and are hyper-parameters of the algorithm. Numerous variants exist, such as varying the stepsize above along the iterations.
16.3 Projected gradient descent
Oftentimes, we seek to find the solution of a minimization problem subject to constraints on the variables, of the form where is a set of constraints. We say that an approximate solution to Eq. (16.3) is feasible if . Naturally, the design of algorithms for the constrained setting now depends, not only on information about , but also on information about .
Similarly to , different oracles can be considered about . One of the most commonly used oracles is the Euclidean projection
Definition 16.2 (Euclidean projection)
The Euclidean projection onto the set is defined by
This projection, which is well-defined when is a convex set, can be used in projected gradient descent, that we briefly review below. Typically, the projection on a particular set requires a dedicated algorithm to compute it.
Other possible oracles are linear maximization oracles (LMO) used in Frank-Wolfe algorithms and Bregman projection oracles, used in mirror descent algorithms. The algorithm choice can be dictated by what oracle about is available.
16.3.1 Variational perspective
Projected gradient descent is a natural generalization of gradient descent, based on the Euclidean projection oracle. Its iterates read At each iteration, we attempt to decrease the objective by moving along the negative gradient direction, while ensuring that the next iterate remains feasible, thanks to the projection step.
Similarly to the variational perspective of gradient descent in Eq. (16.2), the projected gradient descent update is equivalent to This shows that projected gradient descent minimizes a trade-off between staying close to and minimizing the linearization of around , while staying in .
In terms of convergence rates, they remain the same as gradient descent (Nesterov, 2018). For example, projected gradient descent on a smooth convex function still converges at a rate .
There are numerous extensions of vanilla projected gradient descent. Similarly to gradient descent, the stepsize can be automatically adjusted using linesearch techniques and there exists accelerated variants. If we replace with a stochastic gradient , we obtain a stochastic projected gradient descent.
16.3.2 Optimality conditions
In the unconstrained case, a minimum necessarily has a zero gradient. In the constrained setting, there may not be any feasible parameters with zero gradient. Instead, the optimality of a point is characterized by the fact that no better solution can be found by moving along the gradient at that point, while staying in the constraints. Formally, it means that for any , a minimizer of on satisfies It can be shown that this condition is equivalent (Nesterov, 2018) to
16.3.3 Commonly used projections
We now briefly review a few useful Euclidean projections.
If , we obviously have Therefore, in the unconstrained setting, projected gradient descent indeed recovers gradient descent.
If (box constraints), we have where the and are applied coordinate-wise.
As a special case of the above, if (non-negative orthant), also known as non-negative part or ReLU.
If (unit probability simplex), where is a constant ensuring that normalizes to . It is known that can be found in using a sort. This can be improved to using a median-finding like algorithm.
16.4 Proximal gradient method
The constrained setting (with a convex set) can be recast as unconstrained optimization, by extending our analysis to functions taking infinite values. Let us denote the indicator function of the set by Clearly, the constrained problem in Eq. (16.3) can then be rewritten as This suggests that constrained optimization is a special case of composite objectives of the form where is a convex but potentially non-differentiable function. We assume that we have access to an oracle associated with called the proximal operator.
Definition 16.3 (Proximal operator)
The proximal operator associated with is
This leads to the proximal gradient method, reviewed below.
16.4.1 Variational perspective
With this method, the update reads This update again enjoys an intuitive variational perspective, namely, That is, we linearize around , but keep as is.
The proximal gradient method is popularly used when the objective function contains a sparsity-inducing regularizer . For example, for the LASSO (Tibshirani, 1996), which aims at predicting targets from observations , we set and , where controls the regularization strength. In this case, is the so-called soft-thresholding operator (see below).
Convergence guarantees of the proximal gradient method remain the same as for gradient descent, such as a rate for smooth convex functions.
16.4.2 Optimality conditions
An optimal solution of the problem is characterized by the fixed point equation for all (Nesterov, 2018). In other words, the proximal gradient method (which includes gradient descent and projected gradient descent as special cases), can be seen as fixed point iteration schemes. Such a viewpoint suggests using acceleration methods from the fixed point literature such as Anderson acceleration (Pollock and Rebholz, 2021). It is also useful when designing implicit differentiation schemes as presented in Chapter 8.
16.4.3 Commonly-used proximal operators
We now briefly review a few useful proximal operators.
If , we have Therefore, with this proximal operator, the proximal gradient method recovers gradient descent.
If , we have Therefore, with this proximal operator, the proximal gradient method recovers projected gradient descent.
If , we have where the operations are applied coordinate-wise. This is the so-called soft-thresholding operator.
where is a partition of and denotes the subvector restricted to , then we have which is used in the group lasso (Yuan and Lin, 2006) and can be used to encourage group sparsity.
For a review of more proximal operators, see for instance (Bach et al., 2012; Parikh et al., 2014).
16.5 Summary
From a variational perspective, gradient descent is the algorithm obtained when linearizing the objective function and using a quadratic regularization term.
Projected gradient descent is the algorithm obtained when there is an additional constraint (the Euclidean projection naturally appearing, due to the quadratic regularization term).
When the objective is the sum of a differentiable function and a non-differentiable function, proximal gradient is the algorithm obtained when the differentiable function is linearized but the non-differentiable function is kept as is.
We also reviewed various stochastic gradient based algorithms, including vanilla SGD, SGD with momentum and Adam.